Paper

Masked Visual Actions for Unified World Modeling

A pixel-aligned action interface for video world models: masked trajectories condition one model for both forward prediction and inverse robot-motion synthesis.

arXiv ↗Jul 21, 2026Code ↗

  • robotics
  • world models
  • video prediction
  • model-based planning
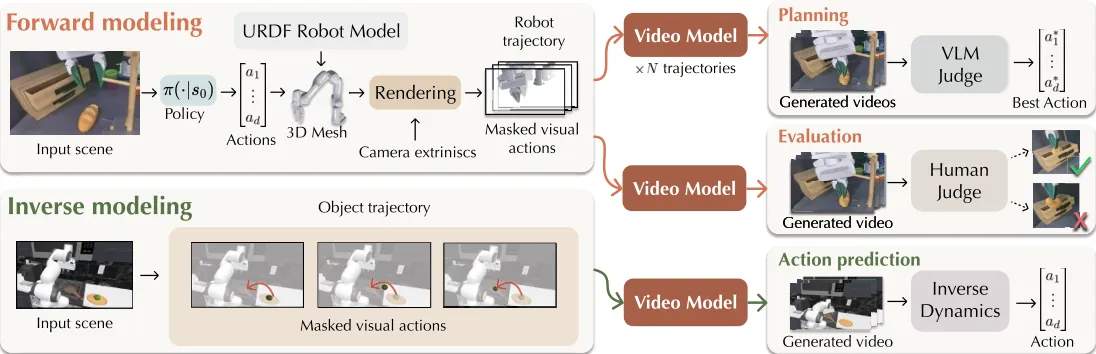
Pipeline diagram showing forward/inverse modeling, planning, evaluation, action prediction workflow

What it is

Finetunes a video model to take masked pixel trajectories as actions, unifying forward scene prediction and inverse robot-motion synthesis in one checkpoint. Instead of low-dim robot commands or sparse visual cues, action is given as masked pixel trajectories. Revealing robot motion yields forward dynamics; revealing object motion makes the same video model infer robot behavior.

Key results

  • DROID: LPIPS 0.0945 vs Ctrl-World 0.362; PSNR 23.74 vs 18.15
  • BEHAVIOR: LPIPS 0.123 vs Ctrl-World 0.196; PSNR 22.90 vs 18.39
  • Planning boosts success by +24%, +26%, +21%, +11%, +9%, +7% across 6 tasks

Pixel-space action conditioning transfers better across embodiments and lets one video model support both simulation and inverse control.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.