Repo

FlowBlock

Runs block-wise diffusion LMs in parallel via wavefront scheduling and packed batched forwards, reusing exact frozen-prefix KV cache with unmodified weights.

GitHub ↗Jul 19, 2026Paper ↗

  • llm
  • diffusion-lm
  • parallel-decoding
  • batched-serving
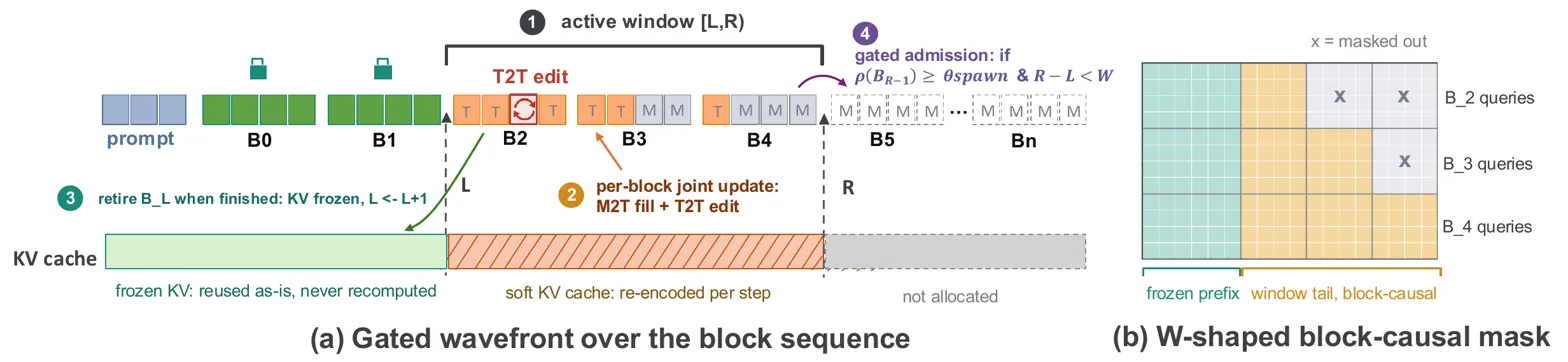
Method diagram showing gated wavefront mechanism and block-causal mask design

What it is

Training-free decoder for block-wise diffusion LMs that parallelizes inter-block generation with wavefront scheduling while preserving or improving accuracy. Parallelize block-wise diffusion LM decoding without retraining by starting downstream blocks from informative drafts, then jointly refining and committing them in order.

Key results

  • Up to 2.95× / 4.01× TPS vs LLaDA-2.1 / 2.0 in batched serving
  • Cuts latency by up to 53.6% / 77.1% vs LLaDA-2.1 / 2.0
  • Improves average accuracy by 1.3 points across 8 math/code benchmarks

Shows that self-correcting diffusion LMs can break strict inter-block serial decoding without retraining.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.