
What it is
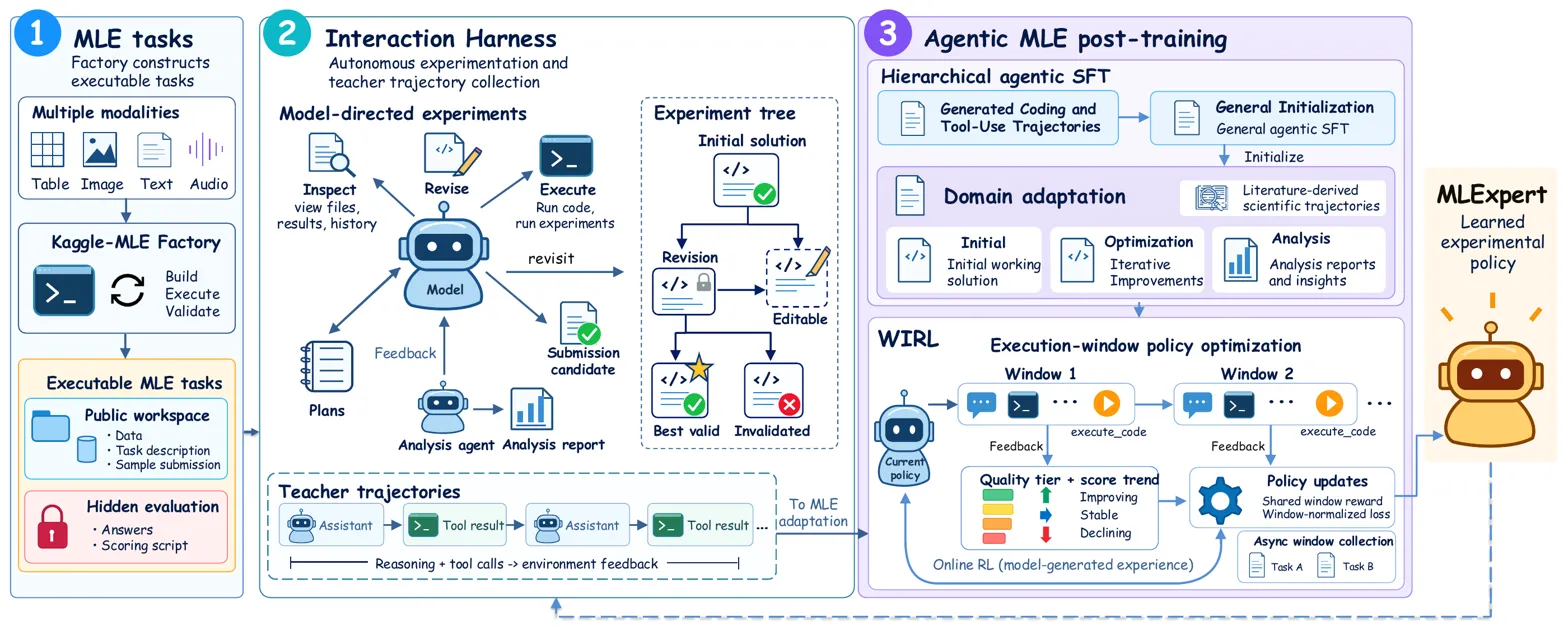
A 35B MoE agentic model for autonomous ML engineering, trained to improve multi-step experiment decisions from execution feedback in long runs. Instead of relying on hand-crafted workflows or single-step training, it trains the model to run long MLE loops itself: hierarchical agentic SFT plus windowed RL that rewards the multi-turn decisions between experiment results.
Key results
- 72.7% medal rate on MLE-Bench Lite vs 37.9% for its base model
- Matches GLM-5.3 and Kimi-K3 at 72.7% medal rate on MLE-Bench Lite
- 84.8% Med+ and 50.0% gold on MLE-Bench Lite
Long-horizon post-training on real experiment feedback can turn a mid-size coding model into a competitive autonomous ML engineering agent.