Paper

Data World: Scaling Data Environments from Scratch

A mechanism-first pipeline that creates synthetic file environments, audited tasks, and rubric rewards from explicit world models rather than existing datasets.

arXiv ↗Oct 15, 2026Code ↗

  • llm
  • agents
  • reinforcement learning
  • benchmarking
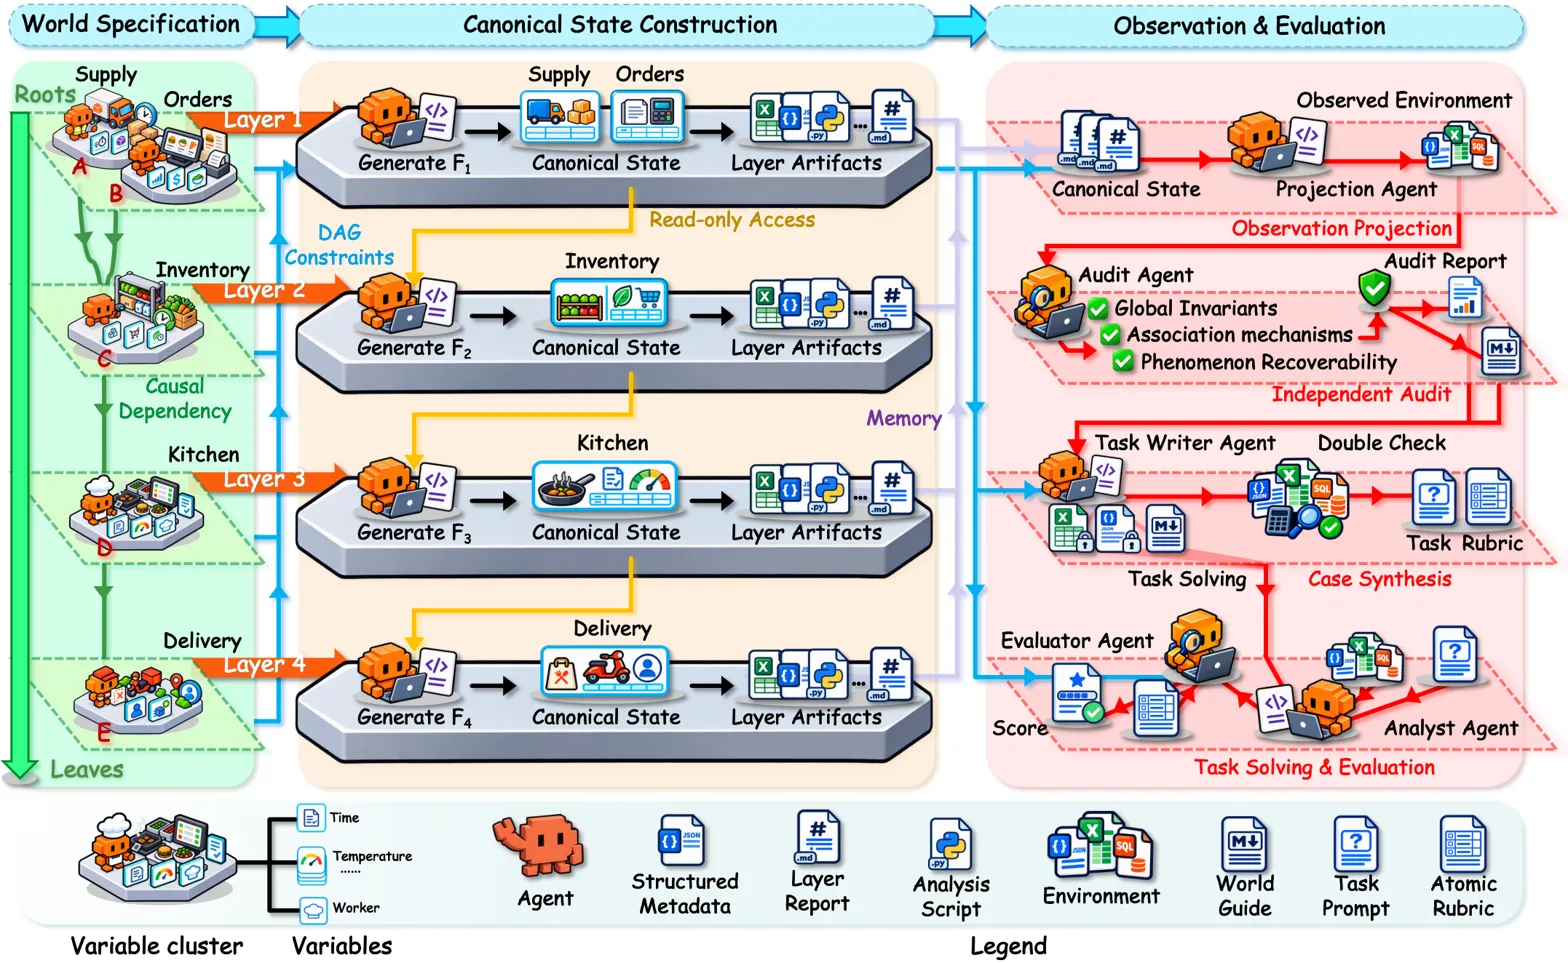
Full pipeline diagram showing world spec, canonical construction, observation and evaluation stages

What it is

Builds synthetic data-analysis worlds by specifying generative mechanisms before files, then uses audited rubrics for benchmarking and RL training of data agents. Instead of mining tasks from existing files, it generates the hidden world first, then projects noisy files and audited rubrics from that truth. This gives checkable open-ended data-analysis tasks and RL rewards without private data or trajectory distillation.

Key results

  • +20.90 on DABstep-Hard over Qwen3.6-35B-A3B
  • +14.28 on DAComp over the base model
  • +7.06 on DataWorld-Bench over the base model

Explicit generative worlds can supply scalable, verifiable supervision for training data-analysis agents on open-ended insight tasks.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.