Paper

LLaDA-Image: Building Strong Image Generators with Fully Open Training Recipes

Builds a strong open image generator by decoupling visual-prior learning from language alignment, then unifies T2I and editing in one DiT.

arXiv ↗Sep 3, 2026Code ↗

  • cv
  • llm
  • image generation
  • diffusion transformers
  • image editing
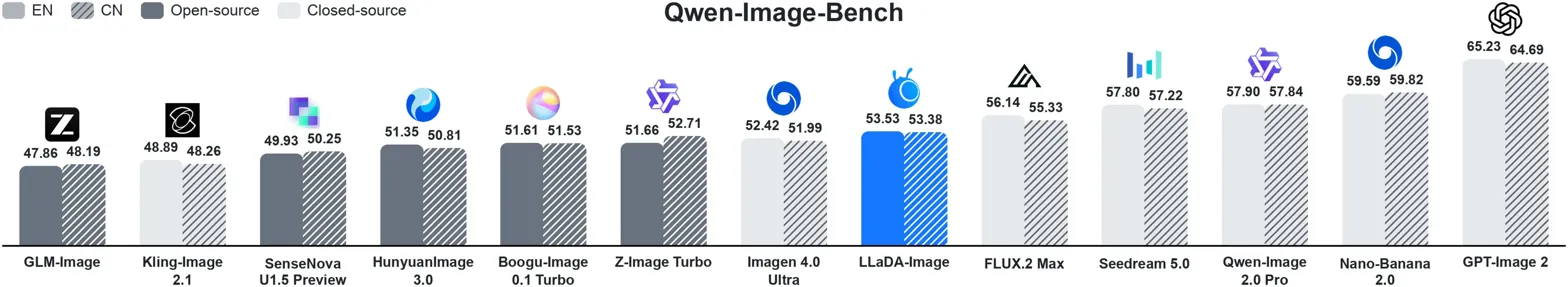
Headline benchmark bar chart comparing Qwen-Image vs baselines on EN/CN scores

What it is

An open 6B DiT image generator trained mostly on real image-only data, then aligned for T2I and editing and distilled to 2-4 step Turbo variants. Instead of caption-heavy training from the start, it learns the visual prior with mostly real image-only data, then adds a frozen dLLM-based VLM for conditioning and distills to 2-4 steps; one checkpoint handles T2I and editing.

Key results

  • 53.53 on Qwen-Image-Bench English, open-source SOTA
  • 53.38 on Qwen-Image-Bench Chinese, open-source SOTA
  • Turbo inference distilled to 2-4 sampling steps

Shows that real-data-dominant image-only pretraining can produce a strong open image generator before later language alignment.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.