
What it is
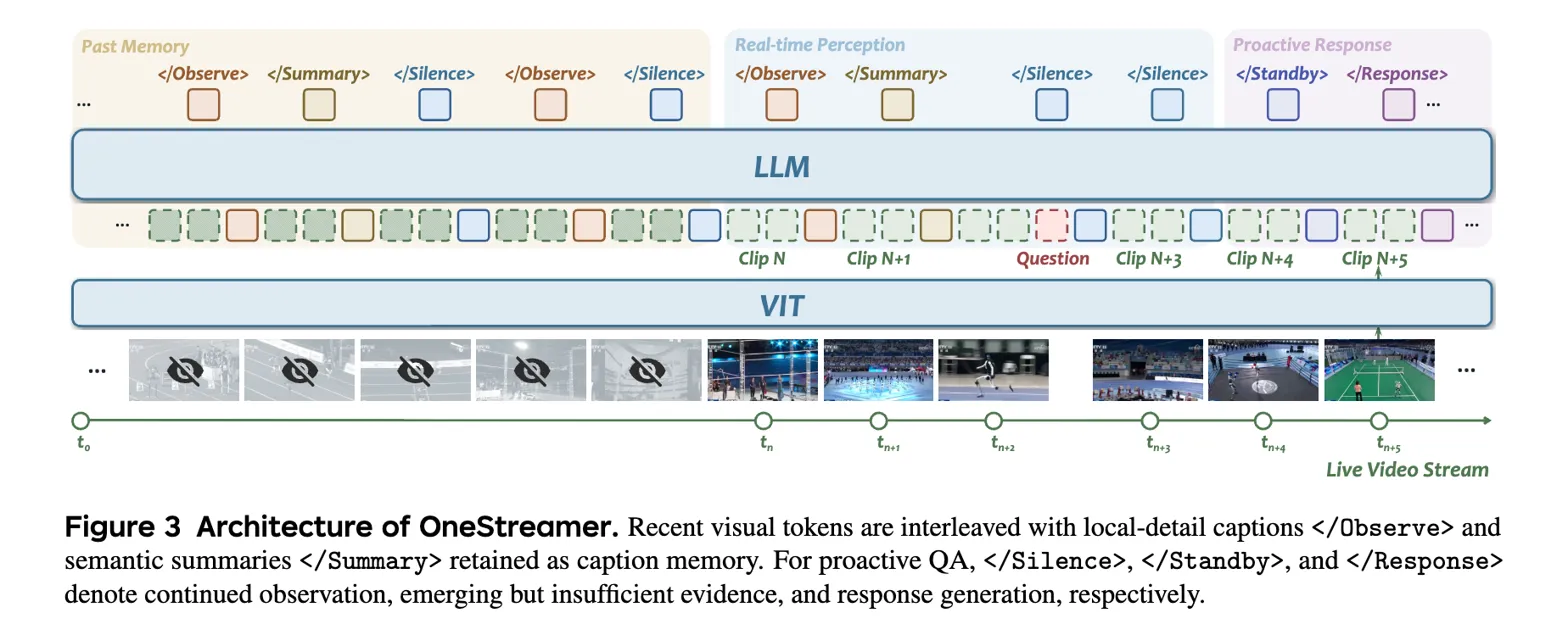
A streaming video LLM that proactively writes reusable caption memory and times responses in one causal generation process. It pairs recent visual context with generated text memory for online QA. Instead of keeping long visual history or only reasoning traces, it writes time-grounded caption memory and answers through the same proactive decoder. It combines a recent visual window with generated local captions and event summaries, plus selective state-token supervision for response timing.
Key results
- Best on all 8 benchmarks; +25.0% avg relative gain vs Qwen3-VL
- OVOBench overall 72.1 vs 65.3 for the strongest listed competitor
- PSTL beats dense supervision while using only 27.5% of state tokens
Shows that generated textual memory can preserve past evidence for streaming QA without hurting real-time perception.