Paper

FDE-Gym: The Last Mile of AI Delivery

A benchmark for ambiguous enterprise delivery tasks that scores deployed solutions by business KPI uplift minus interaction cost, not binary task completion.

arXiv ↗Oct 15, 2026Code ↗

  • llm
  • nlp
  • agent benchmarks
  • enterprise agents
  • evaluation
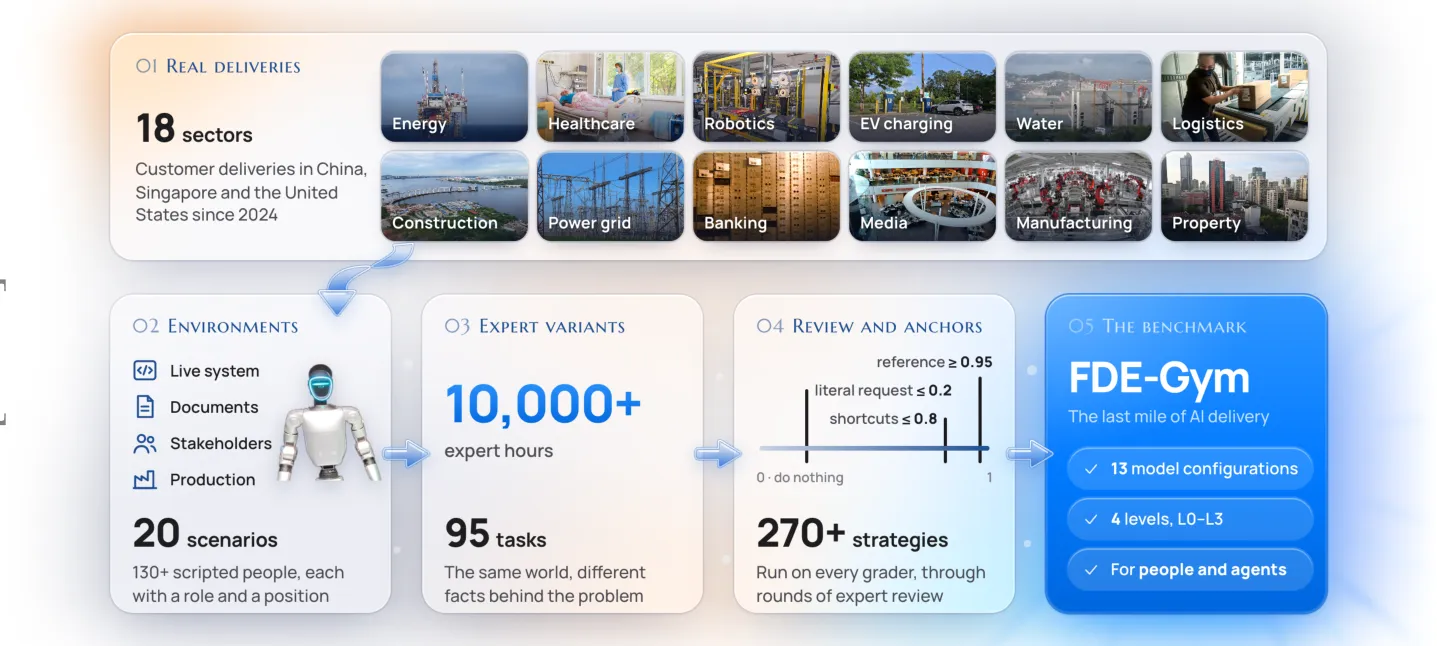
Pipeline diagram showing data sources, environments, tasks, and benchmark construction stages

What it is

A benchmark for forward-deployed AI delivery where agents must clarify ambiguous customer needs, work in live-like systems, and improve business KPIs. Unlike well-specified agent benchmarks, it evaluates end-to-end delivery in simulated customer environments, scoring KPI uplift minus stakeholder-contact cost and testing whether agents can uncover unstated constraints.

Key results

  • Best L3 score is 0.56 mean; only 14 of 95 tasks resolved
  • Oracle per-task model choice still reaches only 0.70 and 30/95 resolved
  • Top models drop from 0.73-0.82 to 0.39-0.62 when constraints must be found

Shows the main gap in enterprise agent deployment is uncovering unstated constraints and turning them into reliable KPI gains.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.