Paper

Language Models that Play Chess and Explain Their Moves

A silent-expert+LM hybrid for chess: cross-attend to engine states, then distill search-consolidated natural-language analyses back into the model.

arXiv ↗Oct 2, 2026Code ↗

  • nlp
  • reasoning
  • distillation
  • game playing
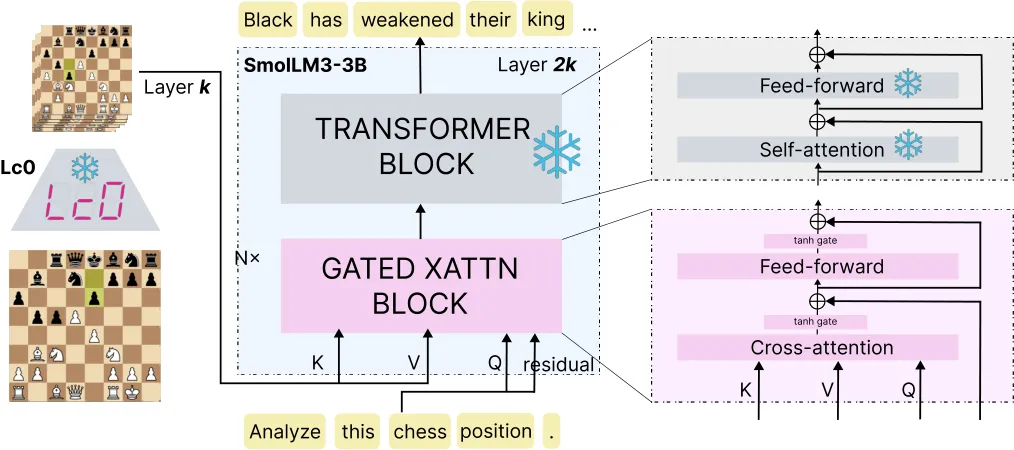
Detailed architecture diagram showing gated cross-attention integrating Lc0 chess with SmolLM3

What it is

A 4B encoder-decoder chess LM that plugs a strong silent chess encoder into an instruction-tuned LM, then iteratively distills search-based explanations to improve play and commentary. Instead of teaching a plain LM chess from text alone, it cross-attends to a strong silent chess encoder, then improves explanations via Bellman-style search distillation from child-position analyses.

Key results

  • 2697 Elo after 7 iterations, up from 1782 (+915 Elo)
  • Beats GPT-5.6-Sol at 2071 Elo and Gemini-3.1-Pro at 2201
  • Higher no-mistake rate on tactical puzzles than all baselines

Shows that coupling an LM to expert latent states and distilling search-improved explanations can raise both playing strength and explanation quality.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.