Paper

Random Attention: Rethinking KV Cache Eviction for Efficient Reasoning

Pins the prompt and randomly keeps non-prompt KV entries per head, replacing score-based eviction with a signal-free policy for reasoning traces.

arXiv ↗Sep 3, 2026Code ↗

  • nlp
  • llm
  • inference optimization
  • kv cache
  • reasoning
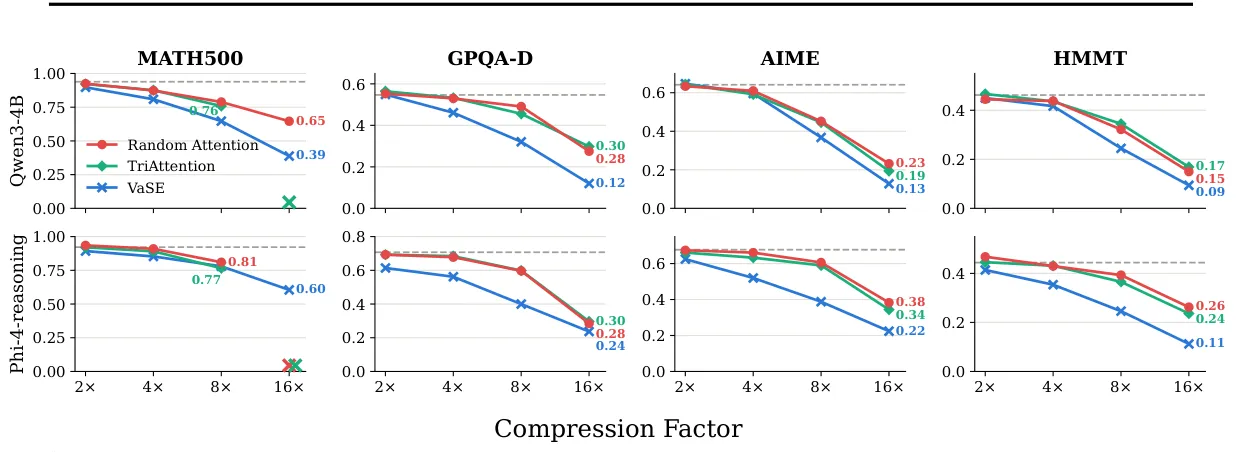
Comparative accuracy vs compression across benchmarks, method vs baselines showing core claim

What it is

A KV-cache eviction baseline for reasoning LLMs that keeps the prompt and randomly evicts the rest per head, matching scored methods while running faster. Instead of scoring cached tokens by predicted future utility, it pins the full prompt and evicts the reasoning trace uniformly at random per attention head. The claim is that prompt protection matters; token scoring mostly does not.

Key results

  • 32-43% higher vLLM throughput than TriAttention at 32k generation
  • Comparable to the strongest prior evictor across 4 models and 6 tasks
  • Significantly ahead in 31 of 60 baseline comparisons; behind in 1

For reasoning-time KV eviction, preserving the prompt dominates accuracy, while the generated trace is redundant enough that random retention is usually sufficient.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.