Paper

Xiaomi-Robotics-1: Scaling Vision-Language-Action Models with over 100K Hours of Real-World Trajectories

Pre-trains a VLA on massive auto-labeled real-world manipulation data, then aligns it to robot bodies and human-style instructions with cross-embodiment post-training.

arXiv ↗Jul 16, 2026Code ↗

  • robotics
  • cv
  • vision-language-action
  • imitation learning
  • mobile manipulation
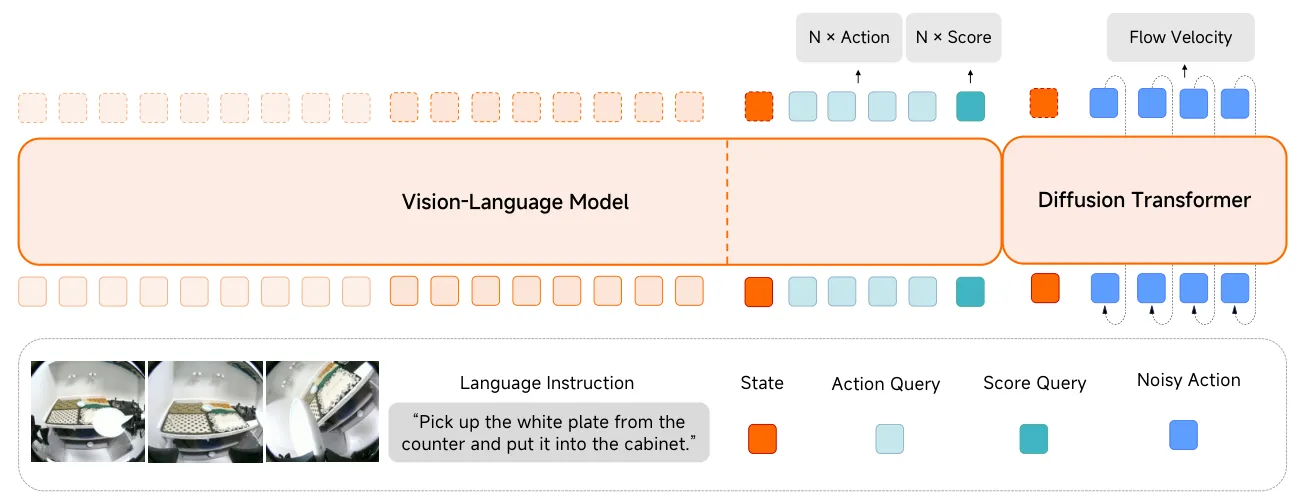
Pipeline diagram showing VLM and Diffusion Transformer processing inputs to actions

What it is

A large VLA model trained with 100k+ hours of real-world trajectories and auto-labeled state-transition language, then aligned to robot embodiments and instructions. Instead of relying on scarce teleoperated robot data with manual task labels, it pre-trains on 100k+ hours of UMI trajectories auto-labeled with state-transition language, then post-trains to map those skills to robot embodiments and imperative instructions.

Key results

  • RoboCasa365: 57.6% success vs prior SOTA 46.6%
  • RoboDojo: 20.07 avg score vs prior SOTA 13.07
  • Real-robot out-of-box success: 75% with full pretrain vs 26% no action pretrain

Shows that scaling real-world action pre-training with automatic language labels transfers to stronger zero-shot robot control and data-efficient adaptation.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.