
What it is
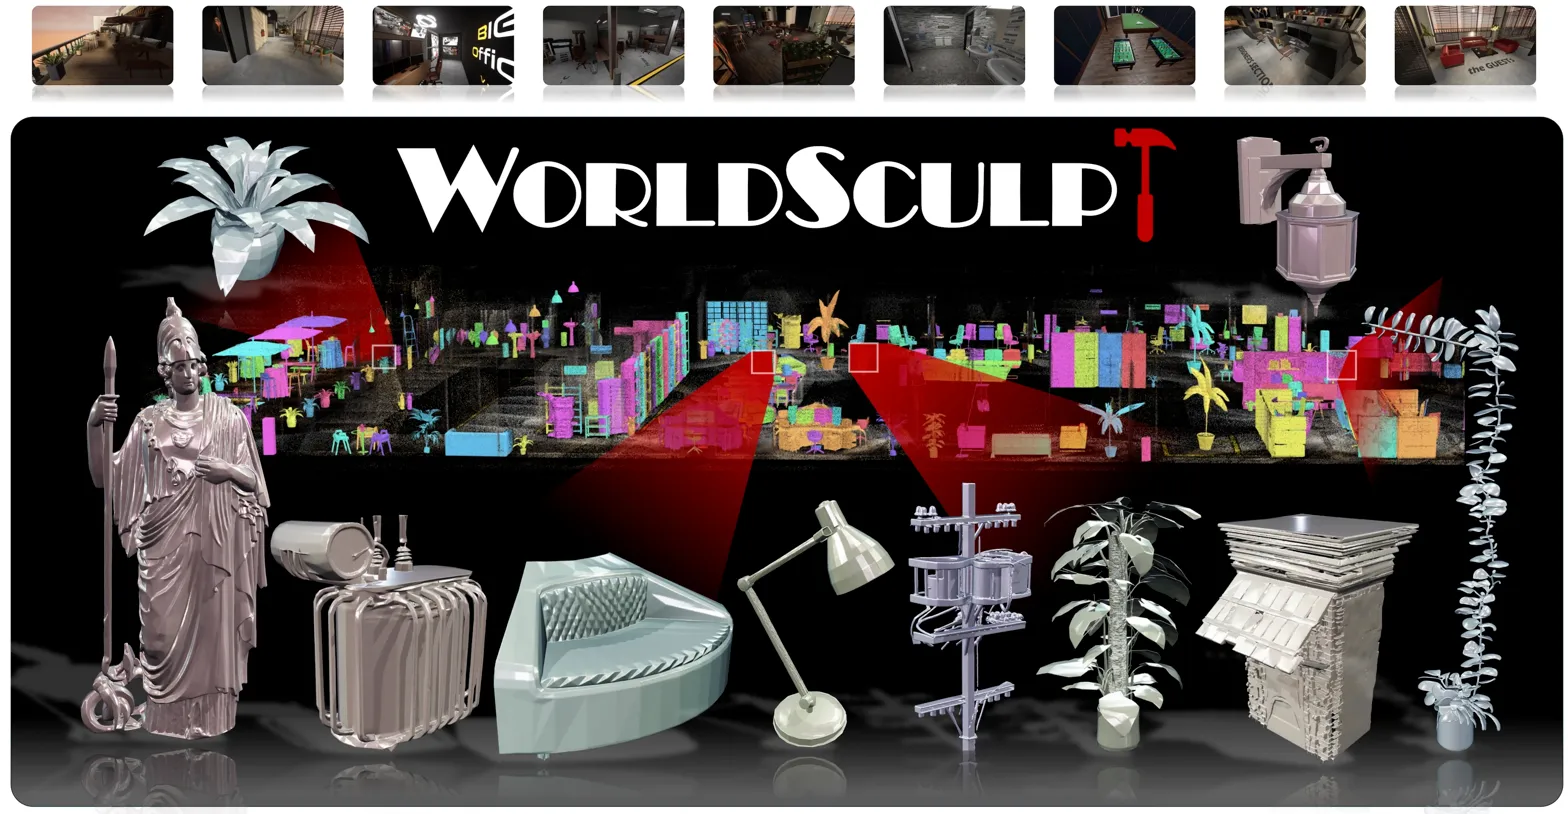
Generates cluttered scenes as separate object meshes from grounded multi-view video by adapting a single-object 3D prior, without scene-level training. Instead of reconstructing one fused scene or training scene-level generators, it conditions a strong single-object 3D prior on posed multi-view object crops in a canonical frame, then places each generated mesh back into world coordinates.
Key results
- Beats prior approaches across single-object, multi-object, and UE-MeshyScene
- Gains grow as scenes become more crowded and heavily occluded
A single-object 3D generative prior can scale to hundreds of occluded scene objects when grounded by multi-view conditioning, without scene-level training.