Paper

MAI-Gym: An Open All-in-One Platform for GUI Agent Evaluation and RL Training across Mobile and Computer Environments

A unified GUI RL platform that shares the exact rollout path for eval and training, and scales learning with synthesized resettable apps and verified tasks.

arXiv ↗Oct 14, 2026Code ↗

  • llm
  • rl
  • gui agents
  • online reinforcement learning
  • benchmarking
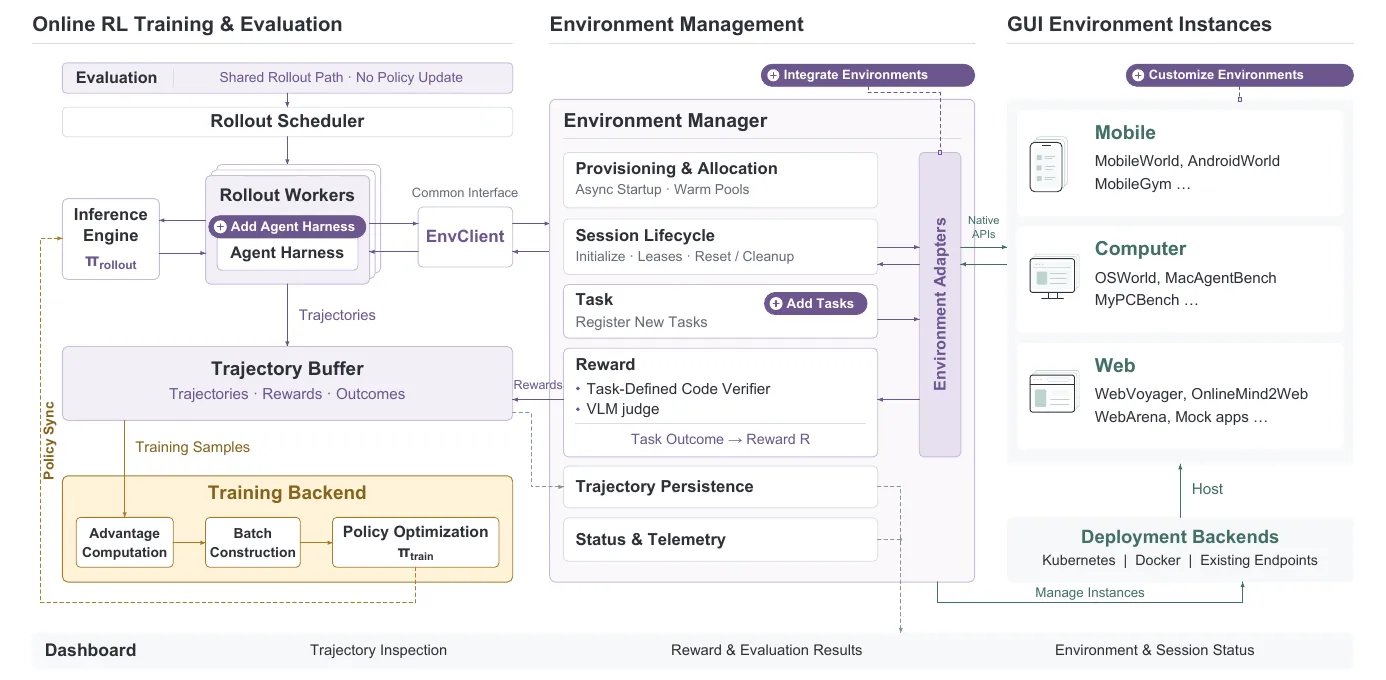
Comprehensive system architecture showing RL training, environment management, and GUI instances pipeline

What it is

Open platform for evaluating and training GUI agents with online RL across mobile, desktop, and web, plus synthesized apps/tasks for scalable learning. Instead of separate eval and training stacks, it uses one shared rollout/harness across both, then adds synthesized resettable apps, cross-app worlds, and execution-validated tasks to scale GUI RL.

Key results

  • 78.4% on MobileWorld, beating UI-Venus-2-9B's 75.2%
  • 76.2% on OSWorld-Verified vs UI-Venus-2-9B's 70.8%
  • Real-phone train app success improved 28.8% to 48.1% after RL

Shared infrastructure plus synthesized, verifiable GUI tasks can make online RL transfer beyond mocked environments to real app use.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.