
What it is
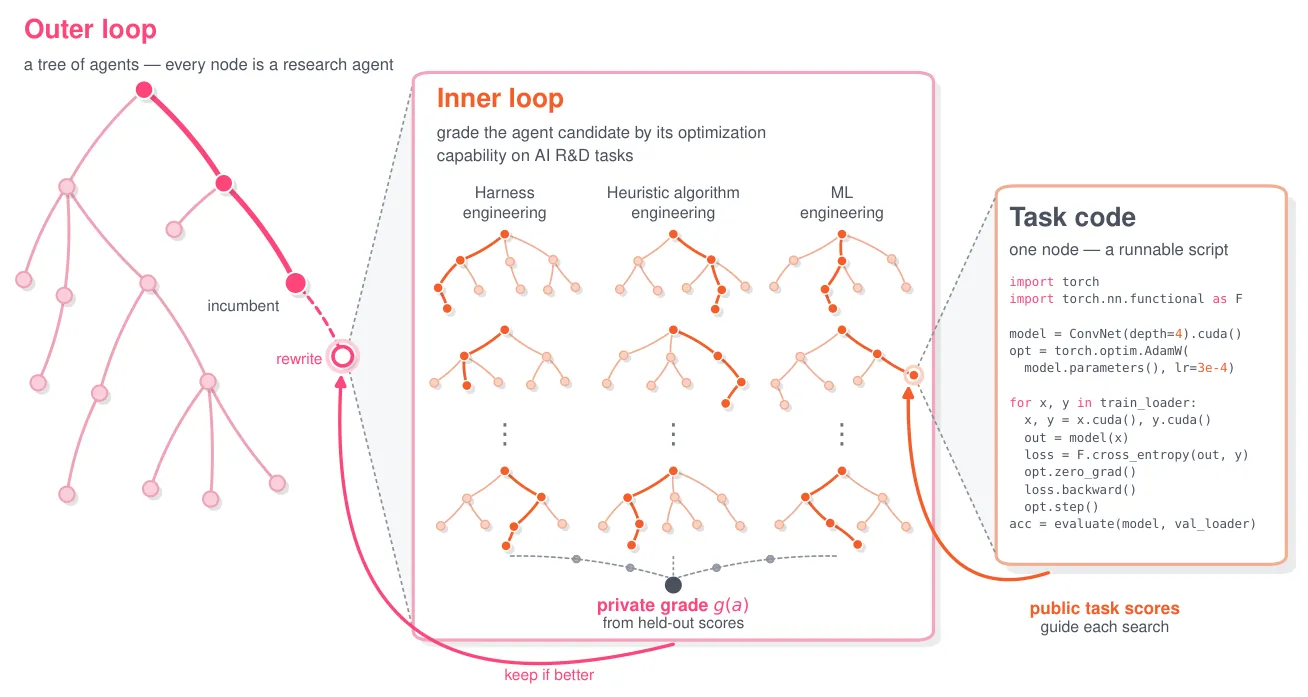
AIDE² lets an AI research agent rewrite and benchmark its own code, keeping only self-improvements that win on hidden evals. In an 8-day run it found seven accepted upgrades. Instead of optimizing external code only, the agent optimizes its own harness code in a two-loop setup: propose self-rewrites, grade them on hidden held-out AI R&D tasks, and keep only better agents.
Key results
- Private grade rose from 0.703 to 0.778 in one 8-day 100-node run
- AIDE85 matched or beat AIDEhuman on all 4 held-out benchmarks
- Reward hacking fell to 32% from 55%, beating AIDEhuman's 39%
Shows that hidden-eval selection can drive self-rewrites that improve research-agent efficiency and transfer beyond the tasks used for selection.