Dataset

OmniVChat

Contains 2,800 English/Chinese dialogues with video+audio user inputs and rubric-scored text replies for native audio-visual dialogue.

Hugging Face ↗Sep 18, 2026Paper ↗Code ↗

  • rl
  • multimodal
  • audio-visual dialogue
  • tiered rubrics
  • multi-turn
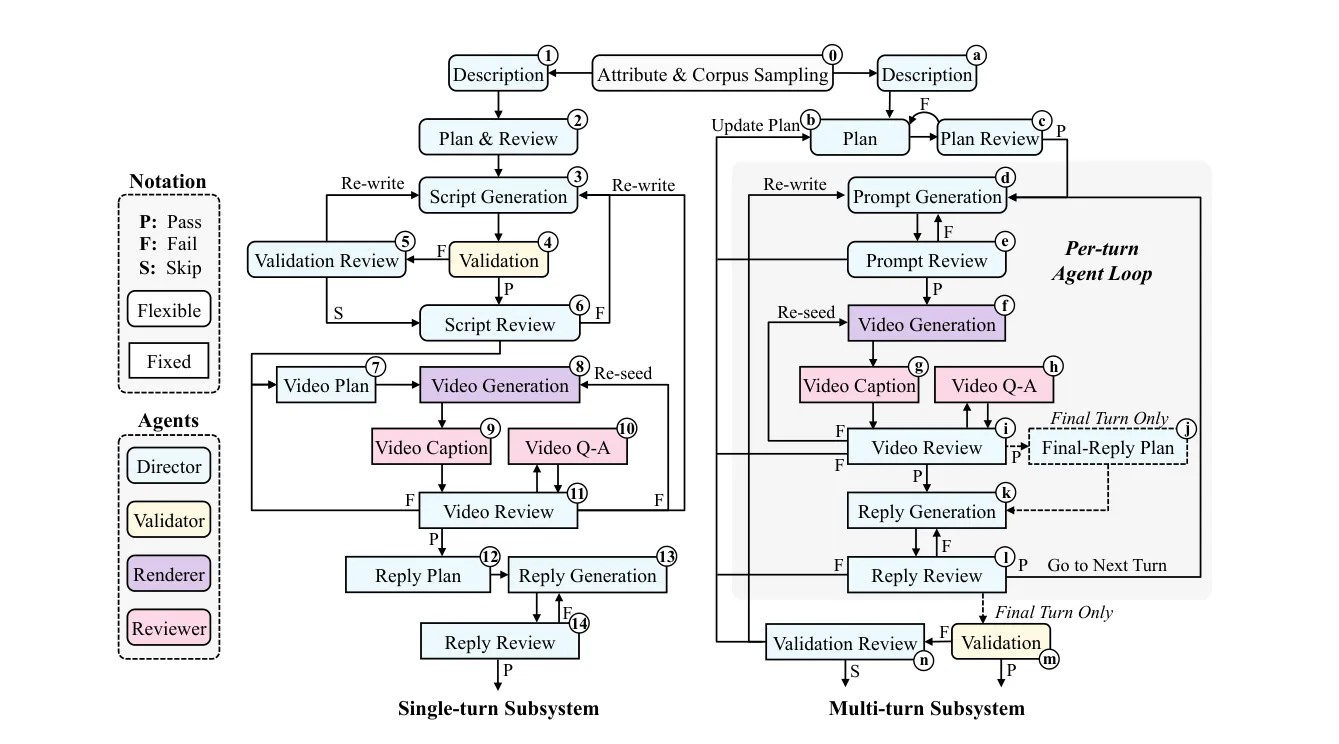
Detailed pipeline diagram showing single-turn and multi-turn subsystems with agent roles

What it is

2,800 audio-video dialogues with tiered rubrics for benchmarking native audio-visual chat, plus a shared reward recipe for RL training. 2,800 audio-video dialogues across 5 abilities, 17 subcategories, and 22 domains, with tiered rubrics for single- and multi-turn evaluation plus a shared reward implementation for RL training.

Key results

  • 2,800 dialogues: 2,550 single-turn + 250 multi-turn
  • 5 abilities, 17 subcategories, 22 scenario domains
  • 3,490 1080p MP4s, ~28 GB, CC-BY-NC-ND-4.0

Useful for benchmarking and reward-model training for models that answer directly from synchronized video and audio.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.