Paper

PACT: From Credit Assignment to Critic Alignment

A theory-led actor-critic method that replaces lagging critic updates with actor-then-critic training using importance-corrected value targets.

arXiv ↗Sep 22, 2026Code ↗

  • llm
  • reinforcement learning
  • actor-critic
  • reasoning
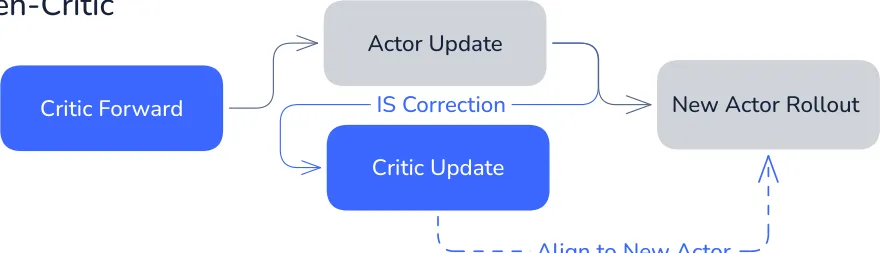
Pipeline diagram showing actor-critic method flow with IS correction and alignment

What it is

Defines a unique token-level credit for LLM RL and turns it into PACT, an actor-then-critic update that aligns critic targets to the updated policy. Instead of treating token credit as heuristic, it proves a unique credit under three axioms and uses that to redesign actor-critic training: update actor first, then train the critic with importance-corrected targets aligned to the new policy.

Key results

  • 72.87% avg math accuracy, beating GRPO by 8.80 pts and PPO by 13.16
  • 67.4% SWE-bench Verified pass@1, +2.0 over GRPO and +2.4 over PPO
  • 83.12 on AIME 2025, above GRPO's 76.50

Shows that critic-policy misalignment is a major bottleneck in LLM RL, and fixing it materially improves long-horizon reasoning and coding.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.