Paper

The Tasteful Agent: Measuring and Improving Taste in Long-Horizon Tasks

A trajectory-mined benchmark measures long-horizon choices at decision forks, then trains better judgment by distilling teachers that saw outcomes.

arXiv ↗Sep 22, 2026Code ↗Dataset ↗

  • llm
  • agent evaluation
  • benchmarking
  • distillation
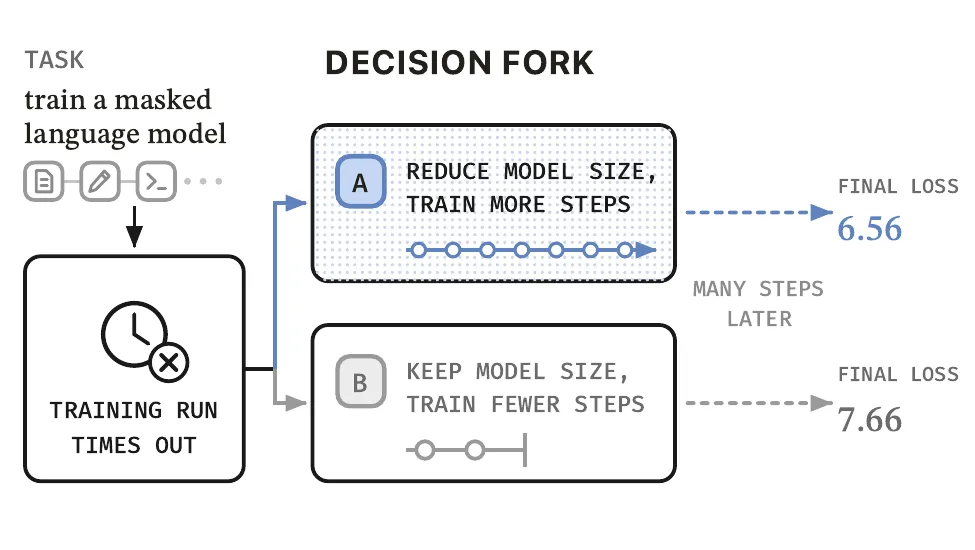
Compares two decision paths with final loss outcomes showing core claim

What it is

Introduces Taste-Bench, a benchmark for long-horizon decision quality in agent trajectories, and shows taste can be improved by distilling hindsight judgments. Instead of scoring only end-to-end success, it isolates decision forks from agent trajectories and tests which branch a model would choose before outcomes are known; taste is then trained by distilling a hindsight teacher's judgment.

Key results

  • Best Taste-Bench accuracy is 59.7% on 502 binary fork questions
  • Mean accuracy drops from 62.3% to 21.0% as evidence moves later
  • More reasoning changes accuracy by only -0.2 pts and +2.2 pts on 2 models

Long-horizon agent quality depends on a distinct decision-making skill that end-to-end benchmarks miss, but hindsight supervision can train it.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.