Dataset

ProgramDistill-Bench

Contains 4,063 packaged web-app repair tasks across 26 applications for restoring missing behavior from code and browser evidence.

Hugging Face ↗Sep 24, 2026Paper ↗

  • llm
  • multimodal
  • coding-agents
  • web-applications
  • executable-evaluation
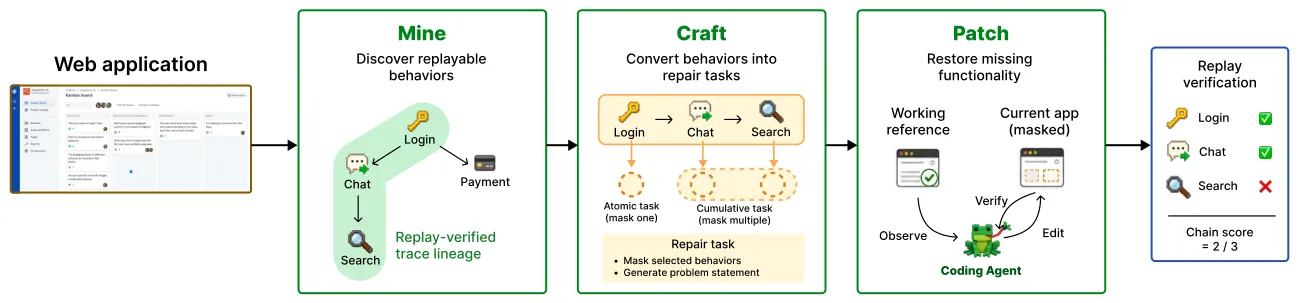
Pipeline diagram showing Mine-Craft-Patch method flow and verification

What it is

Executable benchmark of web-app feature restoration tasks for coding agents, with masked apps, browser traces, verifiers, and reference solutions. 4,063 executable feature-restoration tasks across 26 web apps, plus a 300-task public subset and 12 full reconstructions; each task bundles masked source, reference app, replayable browser traces, verifier, and solution.

Key results

  • 4,063 feature-restoration tasks across 26 apps
  • 300-task public evaluation subset
  • MIT benchmark artifacts; upstream app licenses also apply

Useful for benchmarking coding agents that edit web app code and validate fixes via browser-trace replay.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.