
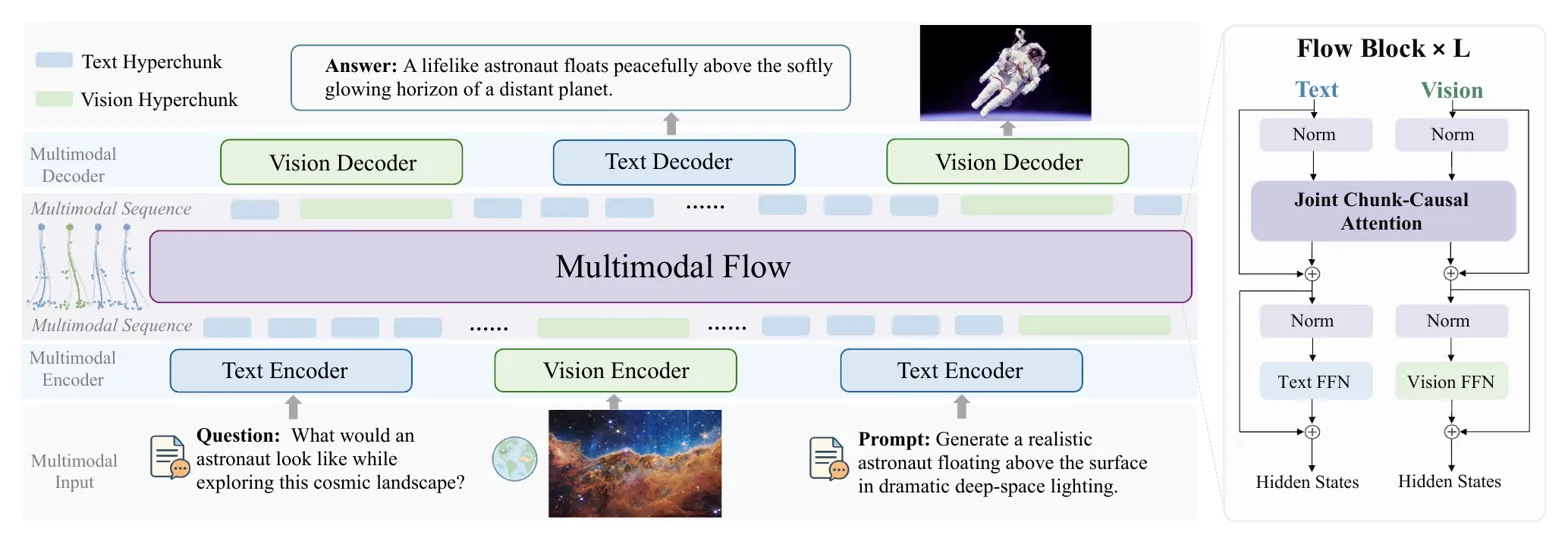
What it is
A unified multimodal generator that models both text and images as continuous embeddings with one flow objective and one sampling process, avoiding image tokenization and hybrid decoding. Instead of discrete image tokens or hybrid text/image objectives, it models both modalities continuously in embedding space with chunk-causal flow. Text blocks and images become ordered hyperchunks, enabling one shared flow backbone for bidirectional generation.
Key results
- 0.821 GenEval, above D-DiT 0.65 and JanusFlow 0.63
- 83.44 DPG-Bench, near SD3 Medium 84.08 and above JanusFlow 80.09
- Under matched budgets: 0.7134 GenEval vs 0.6693 hybrid and 0.3744 discrete
Shows that fully continuous flow modeling can unify language and vision without losing competitiveness on either generation or understanding.