
What it is
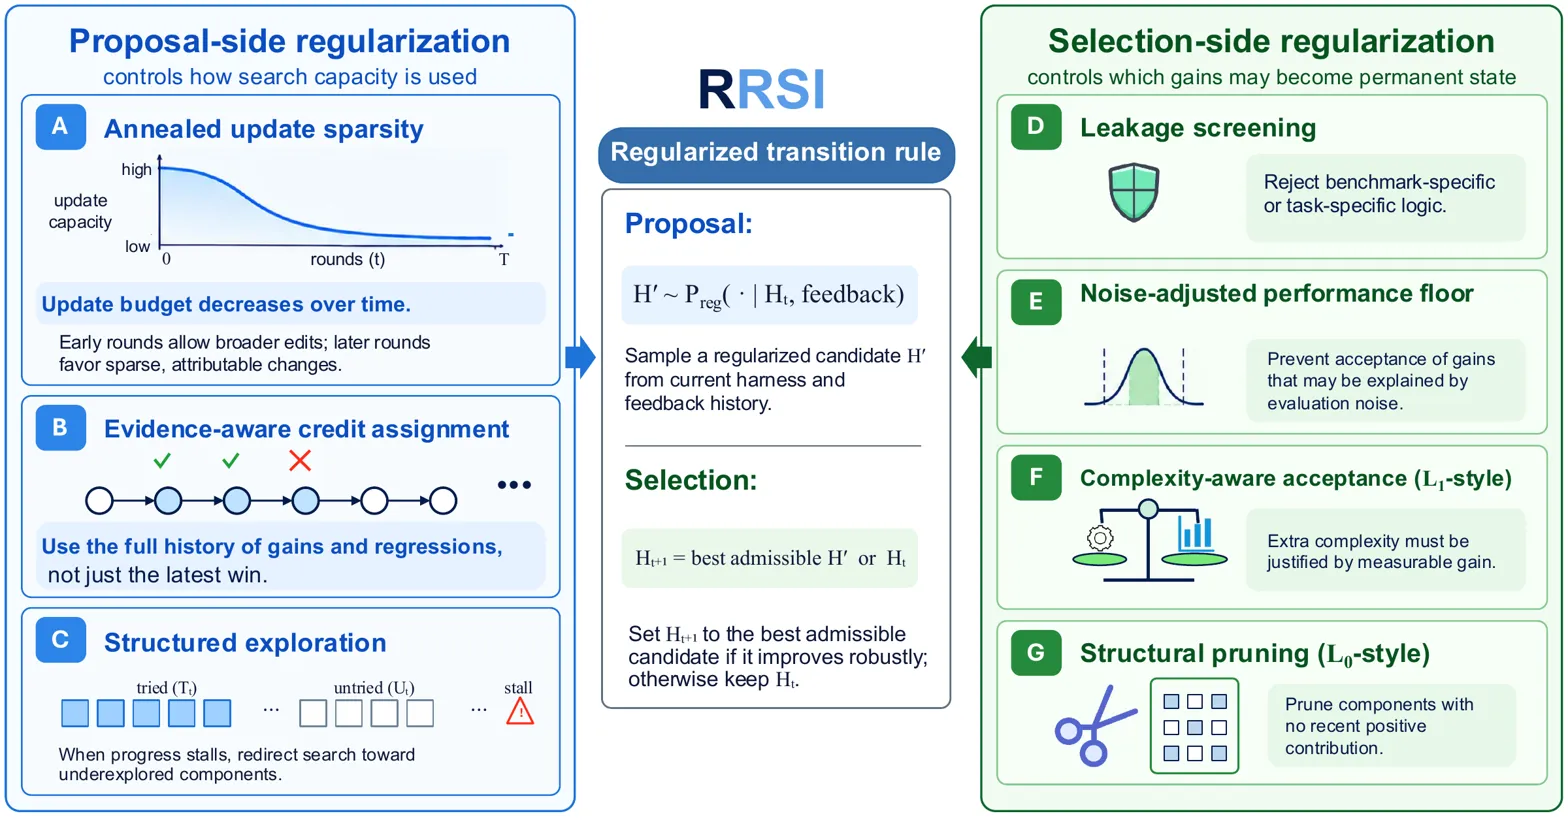
Regularizes recursive LLM-agent harness evolution to avoid overfitting evolve tasks, improving transfer and reducing token cost across coding, workspace, and design benchmarks. Instead of score-only harness evolution that overfits the evolve set, RRSI regularizes both proposal and selection: annealed sparse edits, history-aware exploration, leakage screening, noise-aware acceptance, and pruning favor reusable harness changes.
Key results
- +4.7 on JobBench OOD: 36.0 -> 40.7
- 43.6 OOD avg beats H0 39.7 by +3.9
- 30% fewer policy tokens than unregularized evolution
Shows that regularizing agent-harness evolution improves out-of-distribution transfer and efficiency better than maximizing evolve-set score alone.