
What it is
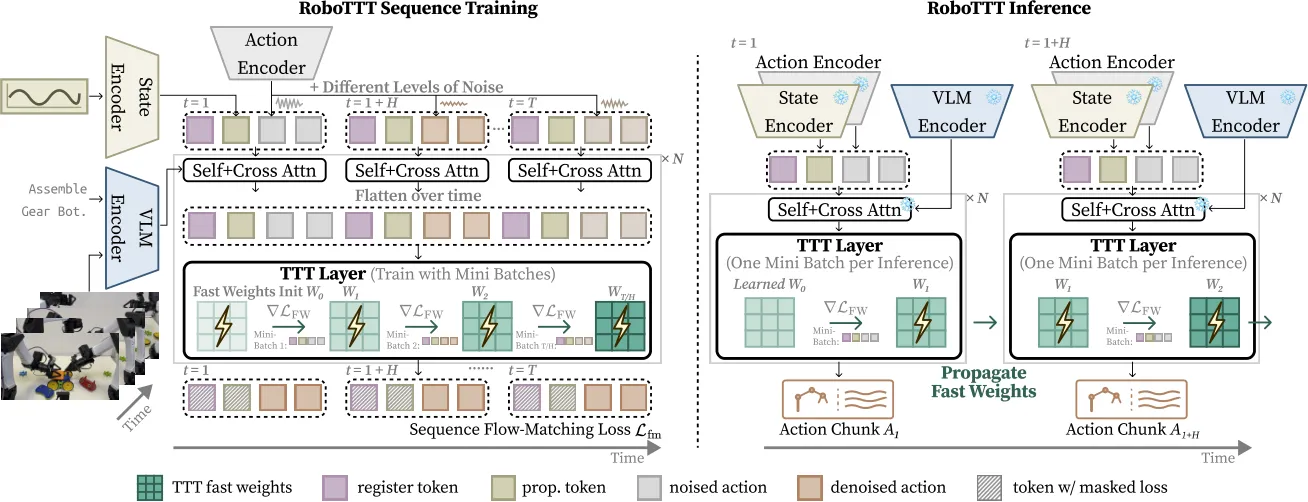
Robot policies use test-time weight updates to compress 8K-step visuomotor history, enabling long-context control and in-context adaptation without higher inference latency. Instead of short-history or memory-only robot policies, it uses test-time training as recurrent fast weights, updating parameters during rollout to store long context and enable in-context imitation and online correction.
Key results
- 79% avg task score vs 42% for single-step GR00T (+87%)
- 83% success under perturbations vs 53% for best short-context baseline
- 6/10 one-shot imitation trials from human video; baselines fail entirely
Scaling robot context through test-time weight updates can materially improve long-horizon control, adaptation, and recovery.