
What it is
A video MLLM for temporal grounding that predicts sets of evidence intervals and trains with interval-set supervision plus a matching-free Wasserstein RL reward. Instead of single-span labels and overlap-only rewards, it treats evidence as an interval set end-to-end: builds verified multi-span long-video labels and optimizes decoded interval sets with exact 1D Wasserstein plus tIoU, avoiding fragile segment matching.
Key results
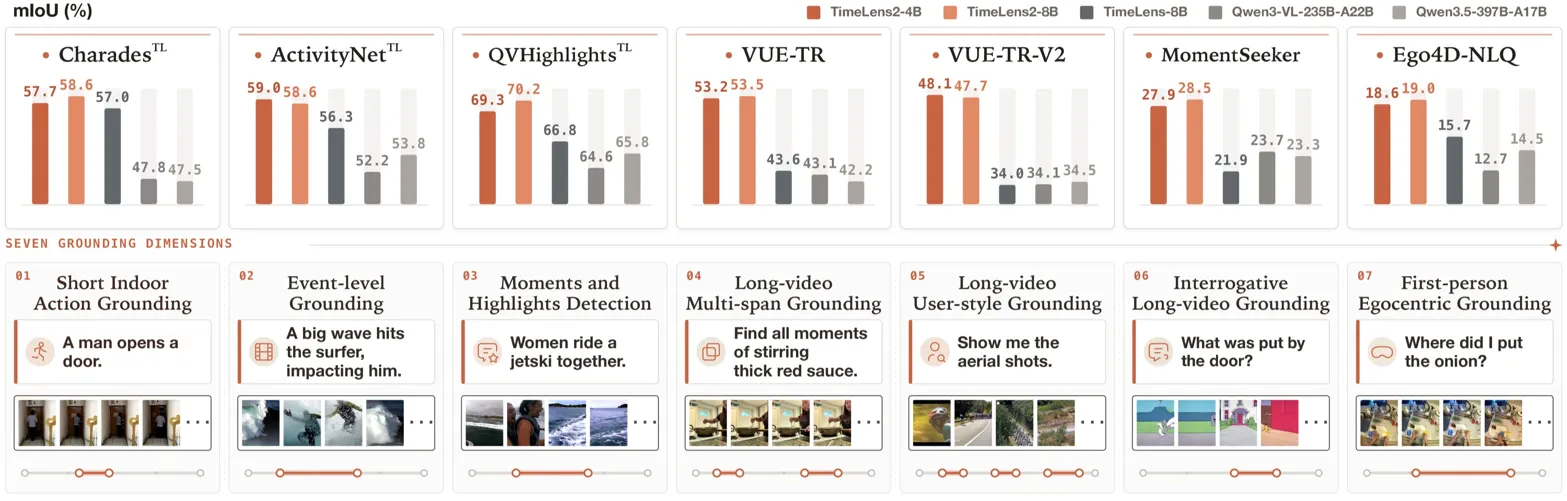
- 4B beats Qwen3.5-397B-A17B on all 7 benchmarks by 7.5 avg mIoU
- 2B/4B/8B improve over Qwen3-VL backbones by 14.2/13.0/18.1 mIoU
- Temporal Wasserstein restores preferences in 75.8% of all-zero-tIoU GRPO groups
Temporal grounding improves when supervision and rewards operate on merged interval sets rather than matched spans or overlap alone.