Paper

Understanding Reasoning from Pretraining to Post-Training

A controlled chess pipeline mirrors LLM pretraining, SFT, and RL to quantify how pretraining sets RL returns and how RL changes reasoning behavior.

arXiv ↗Jul 17, 2026Code ↗Dataset ↗

  • llm
  • nlp
  • reasoning
  • reinforcement learning
  • scaling laws
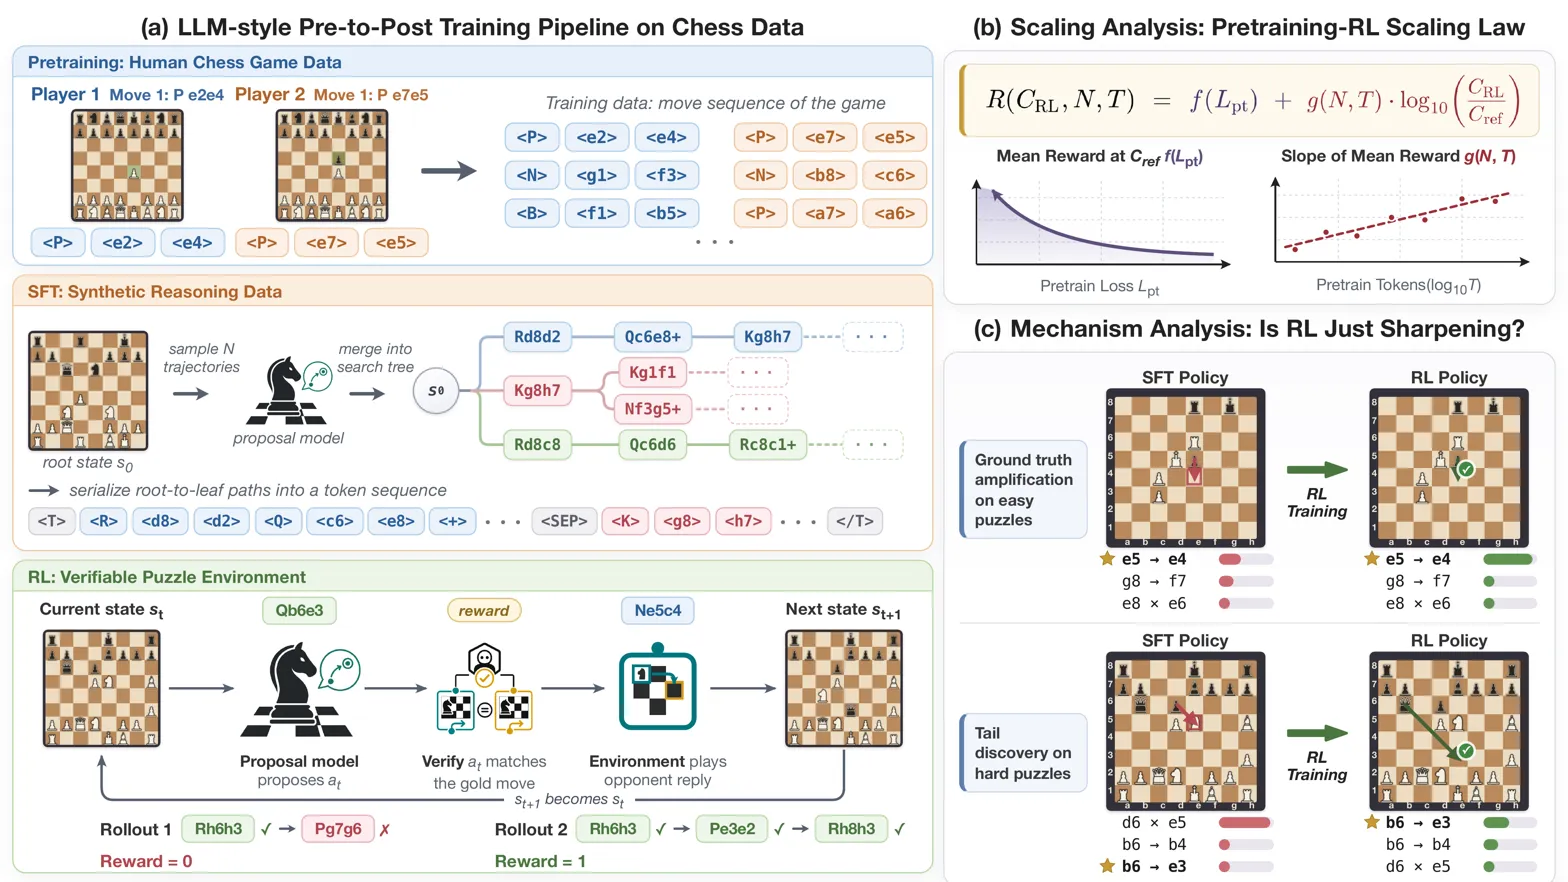
Multi-panel pipeline showing pretraining, SFT, RL method plus scaling law and mechanism analysis

What it is

Studies how pretraining quality and scale shape RL post-training for reasoning, using chess as a controlled LLM-style testbed and a math-domain transfer check. Instead of studying RL post-training alone, it models the full pretrain→SFT→RL pipeline. A controlled chess setup lets them link post-RL gains to pretraining loss/tokens and inspect whether RL sharpens existing policies or discovers rare correct moves.

Key results

  • 36 pretraining-RL combinations across 5M-1B models were analyzed
  • 20M frontier RL compute ratio rises from 5% to 32% as total compute grows
  • A 1B math LM pretrained on 10B-200B tokens shows the same RL scaling pattern

Better pretraining does not just raise the starting point for RL; it also increases how efficiently RL improves reasoning.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.