
What it is
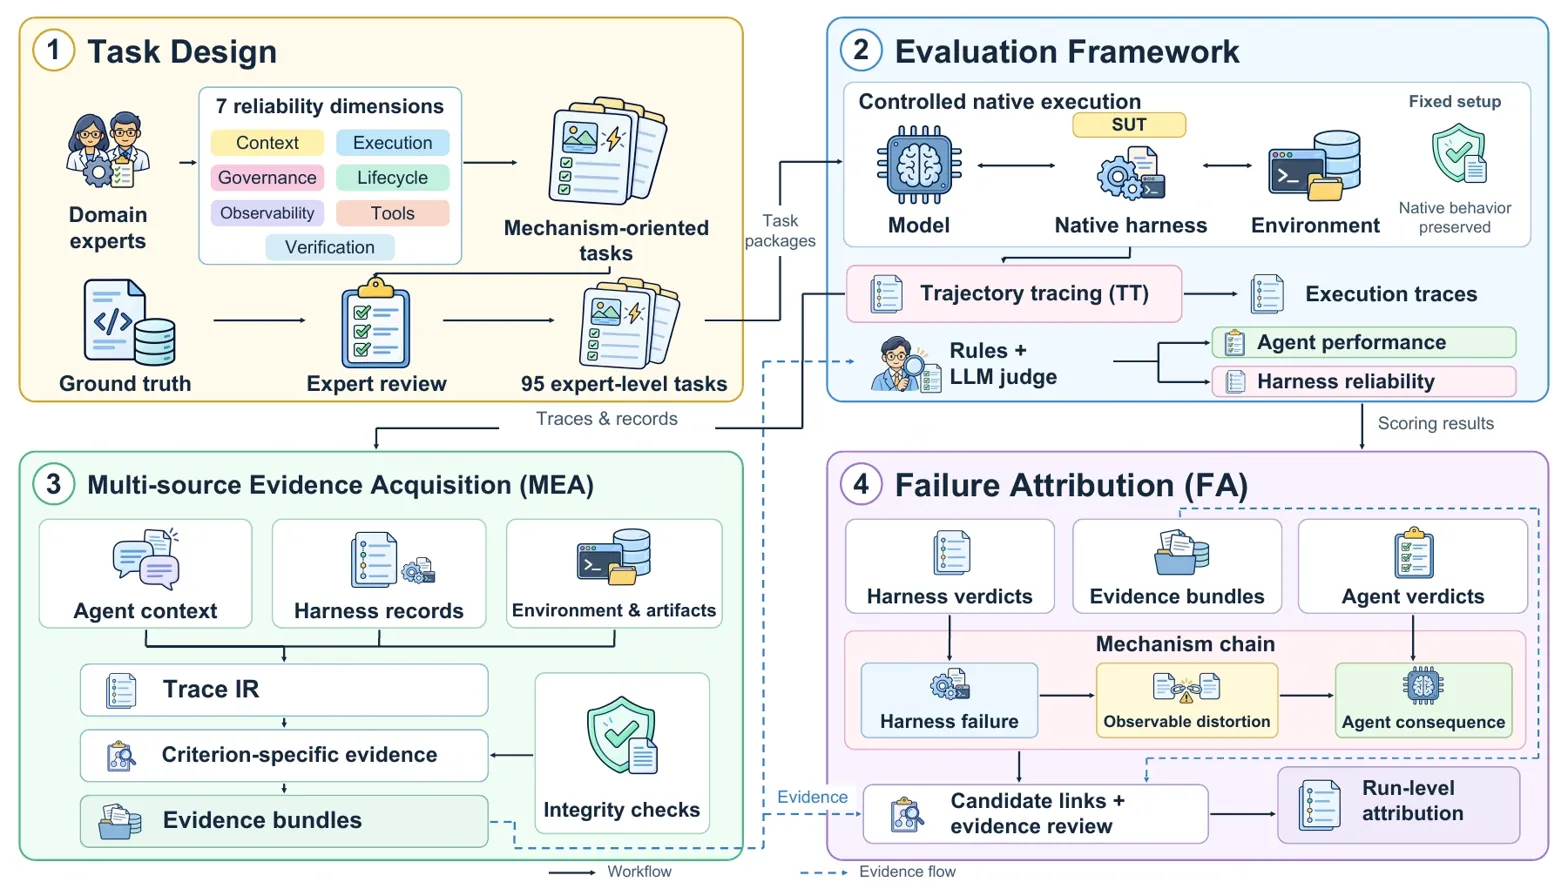
A benchmark for evaluating LLM agent harness reliability separately from task success, using execution traces, evidence bundles, and failure attribution. Instead of scoring only end-task success, it benchmarks the harness itself: 95 mechanism-oriented tasks, trace-based evidence, separate agent vs harness scoring, and explicit failure-attribution links.
Key results
- 31.1% of runs succeeded on task but failed at least 1 harness criterion
- Harness macro scores ranged from 59.8% to 72.0% across 4 harnesses
- Evaluated 3,420 runs over 95 tasks, 4 harnesses, and 9 models
Task outcome alone is a poor proxy for agent-system reliability because models can compensate for harness failures.