Paper

Loop the Loopies!

A layer-looped MoE LLM replaces whole-model recurrence with per-layer recurrence, then trades memory savings for more width at matched training cost.

arXiv ↗Jul 17, 2026

  • nlp
  • llm
  • mixture-of-experts
  • reasoning
  • transformers
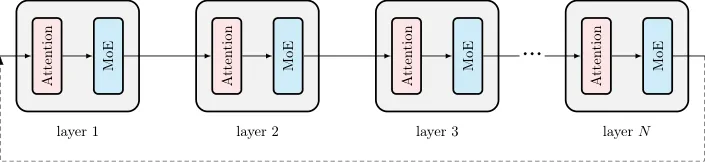
Layered architecture diagram showing Attention+MoE blocks across N layers

What it is

A looped MoE Transformer uses layer-wise recurrence plus a compute-matched scaling recipe to beat vanilla Transformers at the same training cost. Instead of repeating the whole stack like prior looped LLMs, it loops each layer locally and uses the saved activation memory to widen the model under the same wall-clock pretraining budget.

Key results

  • 92.10% on AIME, above Qwen3-30B-A3B-Thinking at 90.10%
  • 94.21% on AMC, above gpt-oss-20B-High at 91.05%
  • 84.72% on IFEval, above Nemotron-3-Nano-30B-A3B at 77.05%

Shows looped transformers can outperform larger vanilla baselines when recurrence is paired with the right compute-matched width-depth tradeoff.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.