Paper

Scaling in Games: Continued Pre-Training For Embodied Agents In Diverse Virtual Worlds

A controlled CPT scaling study for game agents that separates data volume, diversity, and model size, revealing early cross-world interface learning then world-specific gains.

arXiv ↗Oct 20, 2026Code ↗

  • robotics
  • embodied agents
  • imitation learning
  • scaling laws
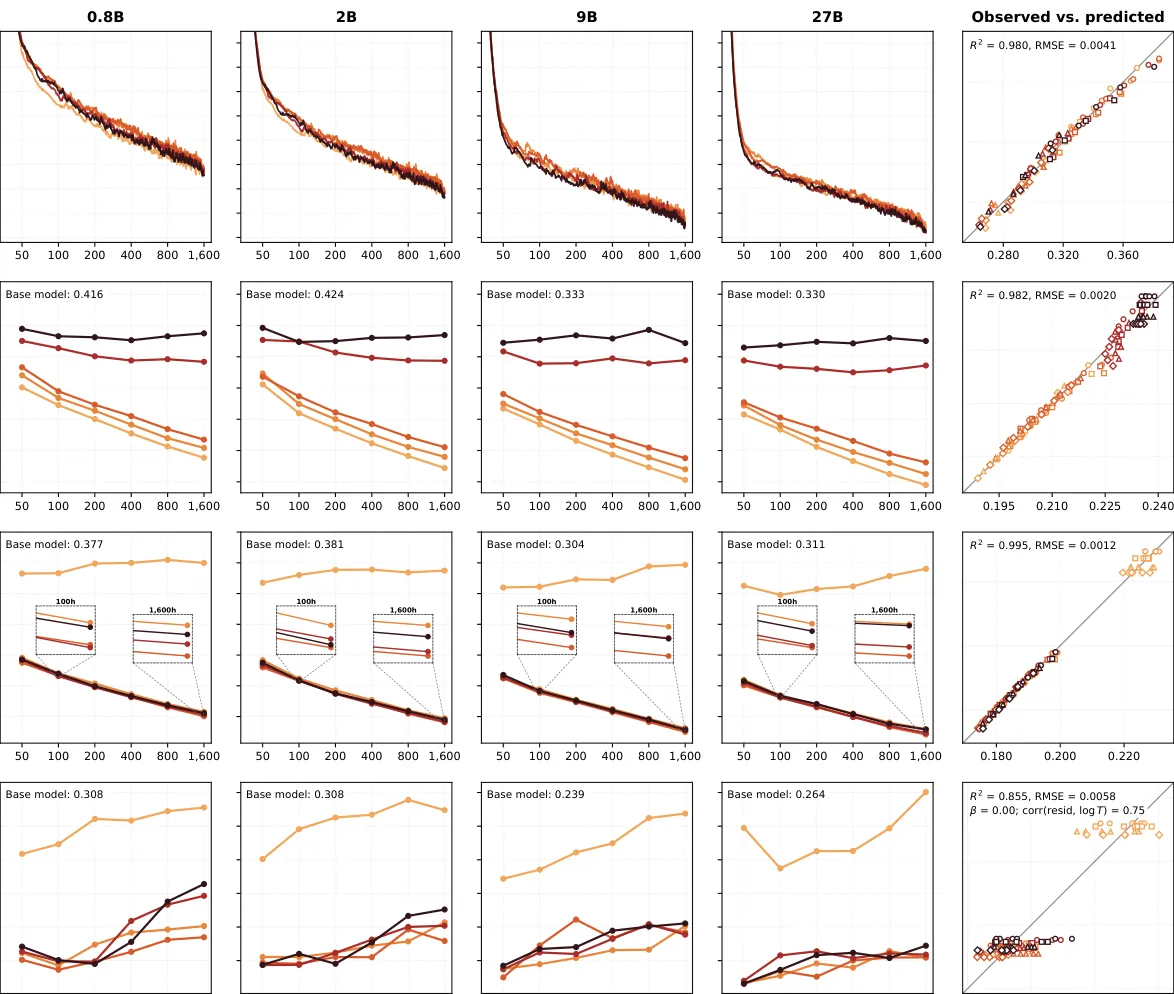
Scaling curves across model sizes with observed vs predicted validation showing core claim

What it is

A controlled 120-run study of continued pre-training for game agents, isolating data volume, diversity, and model size across virtual worlds. Instead of scaling game agents with entangled recipe changes, it isolates data, diversity, and model size in CPT and shows a two-phase pattern: early shared interface learning, then world-specific gains. Diversity helps transfer to related games, not distant ones.

Key results

  • Scaling law fits: R² 0.995 in-corpus loss and 0.982 Minecraft loss
  • At 1,600h, mixed-data S2-S5 average ~2.8× OGA score vs S1
  • 27B-S1 drops below its base model on all 3 non-Minecraft benchmarks

Continued pre-training mainly builds transferable control primitives early; sustained generalization needs diverse worlds and still breaks on distant ones.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.