
What it is
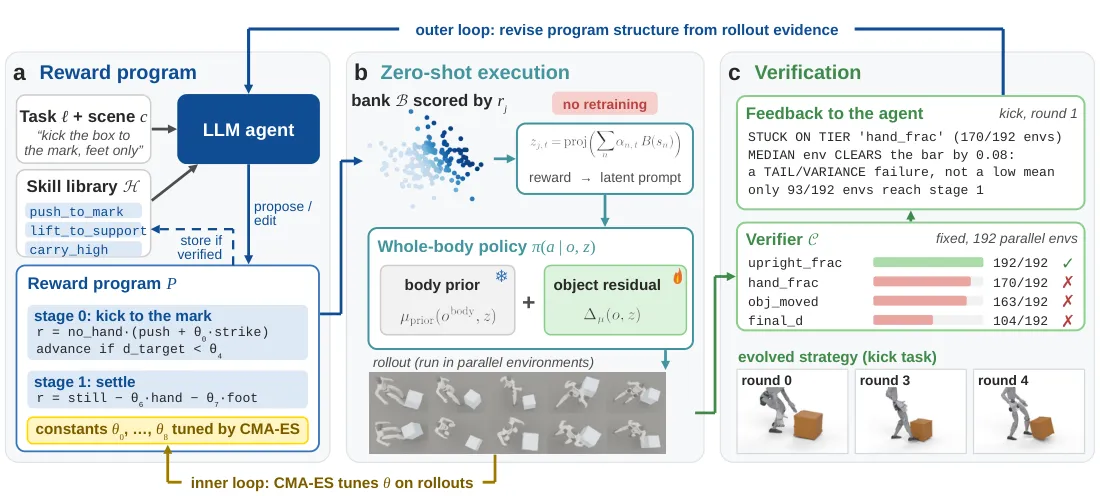
Adapts a frozen humanoid loco-manipulation controller to unseen tasks by evolving staged reward programs at test time, guided by rollout feedback and an LLM. Instead of retraining a policy for each new task, it searches over staged reward programs that a fixed object-aware FB controller can execute immediately. An LLM edits program structure from rollout feedback, while CMA-ES tunes constants and verified programs are reused as skills.
Key results
- Produces diverse unseen-task behaviors in simulation without retraining
- Solves long-horizon composed tasks by reusing verified reward programs
- Selected evolved skills run autonomously on a physical Unitree G1
A broad pretrained humanoid controller can be repurposed for new contact-rich tasks by evolving executable reward programs at test time.