Paper

DriveZero: End-to-End Driving Beyond Human Demonstrations

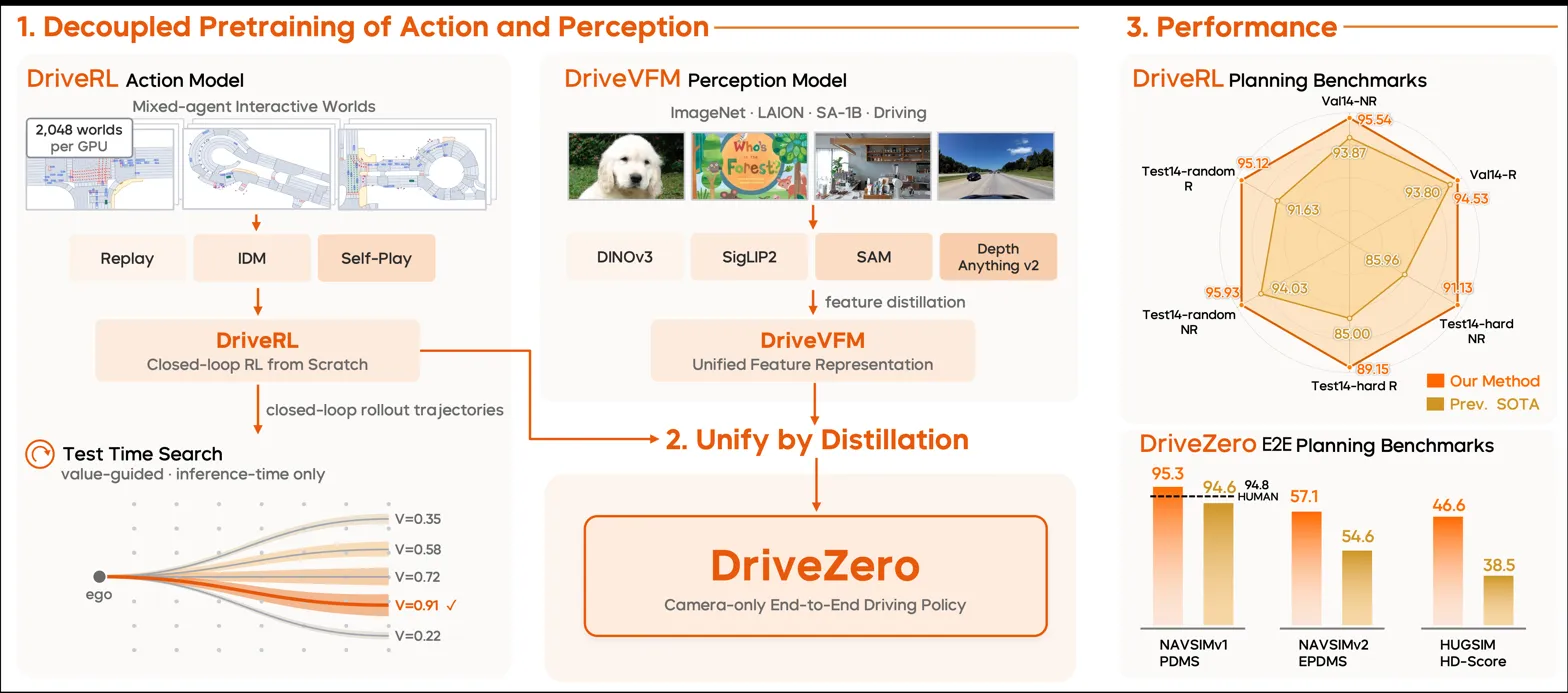
Decouples action and perception pretraining: RL learns a privileged driving teacher, multi-VFM distillation learns vision, then a camera-only student distills teacher rollouts.

arXiv ↗Sep 5, 2026Code ↗

  • cv
  • robotics
  • autonomous driving
  • reinforcement learning
  • imitation learning
Full pipeline diagram plus performance benchmarks showing method vs baselines and human

What it is

End-to-end driving trained beyond imitation: an RL teacher learns in closed loop, a label-free vision backbone learns from frozen VFMs, and a camera-only planner distills the teacher. Instead of learning only from human logs, it splits driving into RL-trained action learning and label-free perception pretraining, then distills the privileged teacher into a camera-only planner with goal-augmented supervision.

Key results

  • 95.3 PDMS on NAVSIMv1 navtest, above human driver 94.8
  • 57.1 EPDMS on NAVSIMv2 navhard, above prior SOTA 54.6
  • 46.6 HD-Score on HUGSIM, above prior SOTA 38.5

Closed-loop RL teacher supervision plus label-free vision pretraining can beat imitation-only end-to-end driving without human trajectory labels.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.