Paper

LaLa-World: Scaling Latent World Models with Natural Language Actions

Uses language as the action interface so one latent world model can train across heterogeneous control and visual data, with an LM predicting future latents.

arXiv ↗Oct 21, 2026Code ↗

  • cv
  • llm
  • robotics
  • world models
  • model predictive control
  • imitation learning
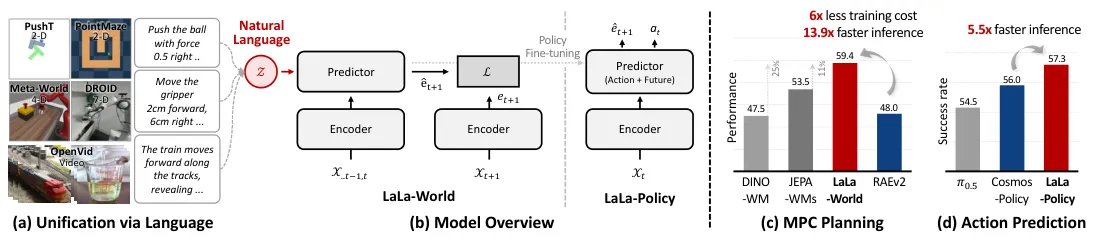
Composite with unification, model overview, and comparative benchmark results showing core claims

What it is

A latent world model that turns actions and visual changes into language, letting one predictor train across robot, sim, image, and video data for planning and policy init. Instead of separate action-specific LWMs or heavier generative video models, it uses language as the shared action interface. Numerical actions are templated into text, and an LM predicts future latents from mixed control, image, and video data.

Key results

  • 72.1% avg MPC success vs 64.6% JEPA-WMs and 62.3% DINO-WM
  • 50.5% avg on Rope/Granular/RoboCasa/DROID vs 44.8% JEPA-WMs
  • Comparable planning to RAEv2 baseline with 6x less train cost, 13.9x faster

Language can unify heterogeneous action spaces and broader visual data without giving up the efficiency advantages of latent world models.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.