
What it is
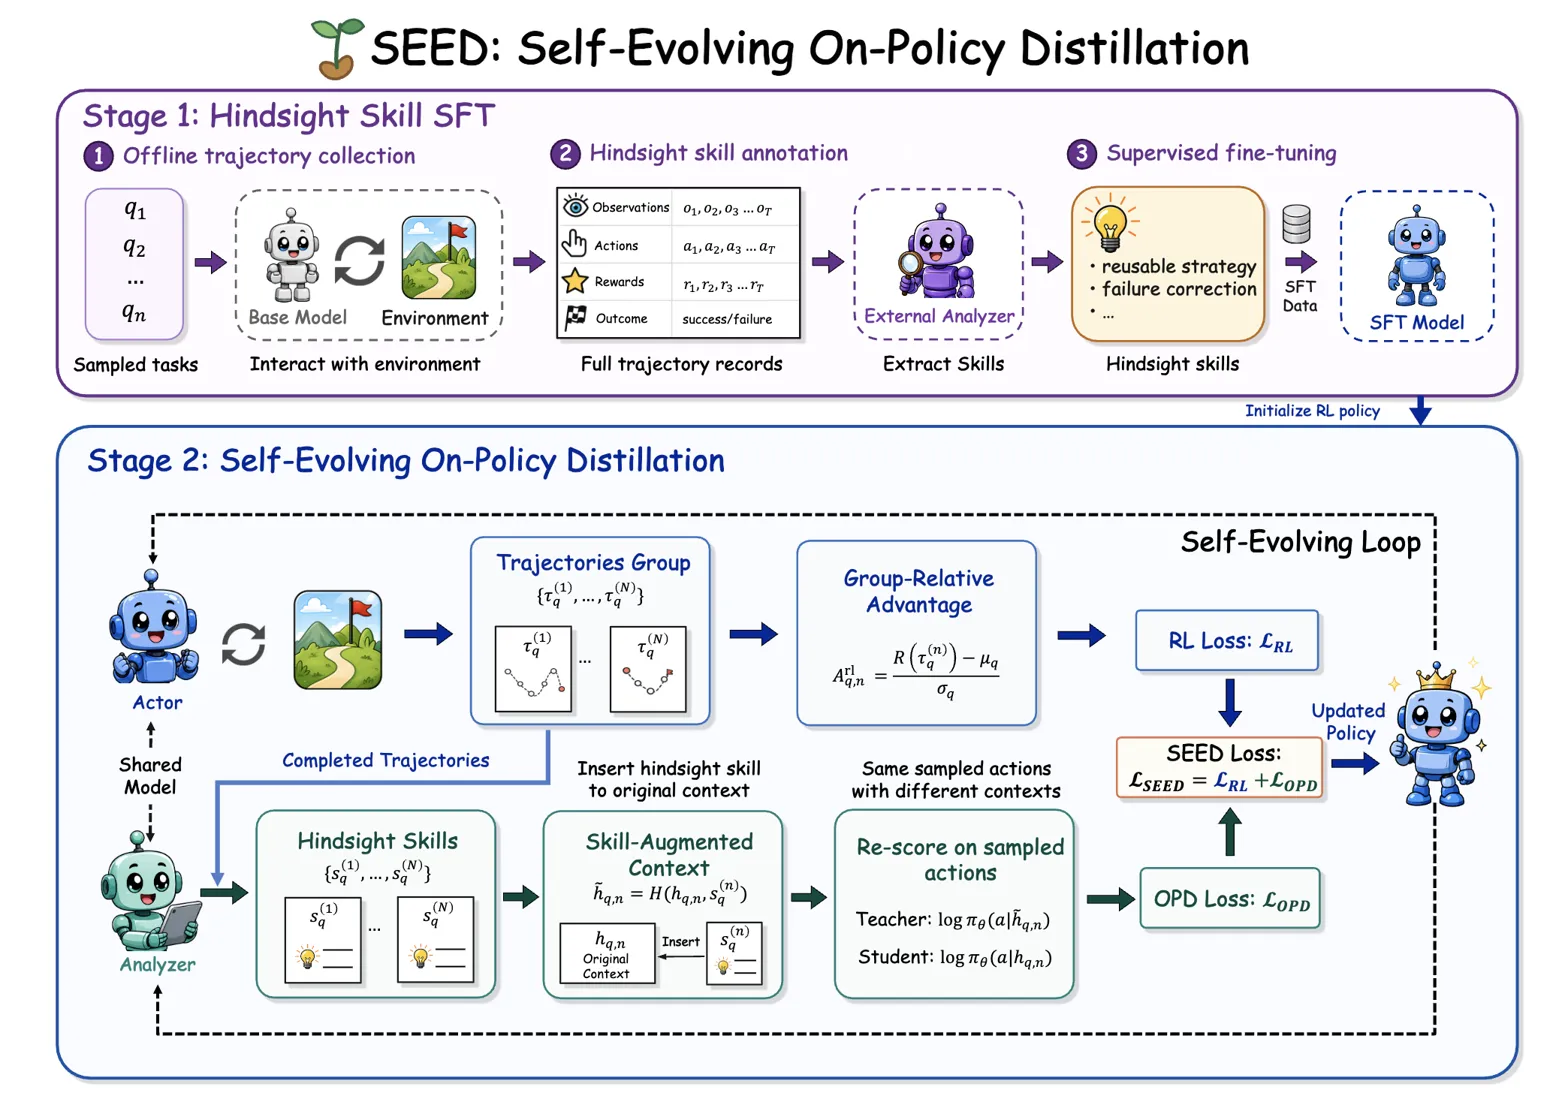
Turns completed on-policy agent trajectories into hindsight skills, then distills their effect as dense token-level supervision during RL for long-horizon LLM agents. Instead of relying only on sparse outcome rewards or static skill prompts, it has the current policy analyze its own finished trajectories into hindsight skills and distills the skill-conditioned probability shift back into the base policy on-policy.
Key results
- ALFWorld avg 91.8 vs 84.4 best baseline
- Search-based QA avg 45.7 vs 44.6 best baseline
- WebShop success 78.9 vs 68.0 best baseline
Shows that self-generated, on-policy hindsight can bridge sparse trajectory rewards and token-level learning without inference-time skill prompts.