Paper

RecreationWorld: Scalable and Verifiable Environments for Hybrid Computer-Use Agents

A recreation-based framework where agents alternate GUI exploration, coding, and self-verification, scored by hidden tests synthesized from a running reference.

arXiv ↗Sep 18, 2026Code ↗

  • multimodal
  • computer-use agents
  • benchmarking
  • agent training
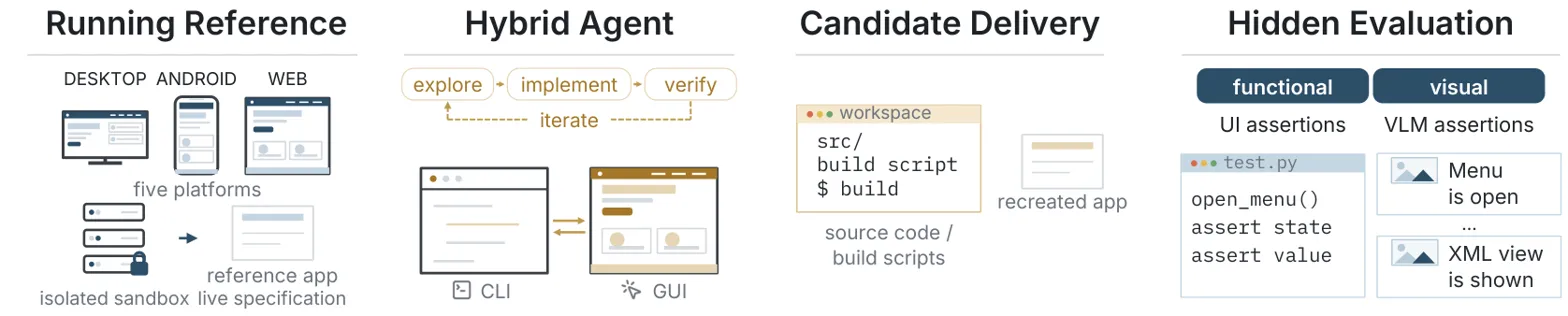
Pipeline diagram showing reference, hybrid agent, delivery, and evaluation stages of method

What it is

Introduces a five-platform framework and benchmark for hybrid computer-use agents that must inspect a running app, reimplement it, and verify behavior automatically. Instead of benchmarking GUI use or coding separately, it uses app recreation: agents explore a live reference, write code, run it, and are scored by hidden reference-derived behavioral and visual tests.

Key results

  • Recreation training improves all 5 OOD benchmarks, with gains up to +17.9 pts
  • GPT-6 Astra leads RecreationBench at 58.1% overall across 250 tasks
  • Full programmatic passes occur on only 2.8% of tasks for GPT-6 Astra

Hybrid agent capability can be trained with execution-grounded recreation tasks, but current frontier models still struggle to reproduce deep interactive behavior reliably.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.