
What it is
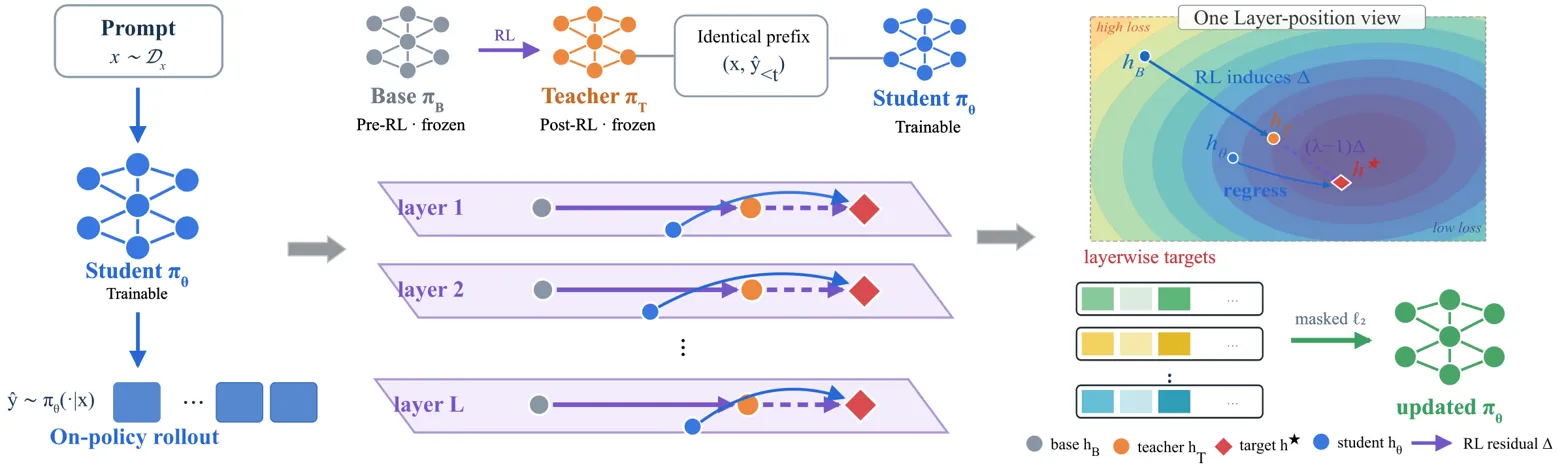
Extrapolates an RL teacher's hidden-state shift from its base model, instead of logits, for on-policy distillation. This lets the student match or surpass the RL teacher more reliably. Instead of extrapolating teacher improvements in output space via noisy log-prob ratios, it extrapolates the teacher's RL-induced hidden-state residual from the pre-RL base at every layer and regresses the student beyond the teacher along that direction.
Key results
- Only method whose mean reaches or beats the RL teacher on all 4 pairs
- Beats OPRD by 0.97-4.06 Avg@16 points across the 4 pairs
- ExOPD trails the untouched student by 14.1 Avg@16 on Qwen3-4B
RL-induced representation residuals are a more stable and faithful direction for beyond-teacher distillation than output-space log-ratio extrapolation.