Paper

RynnVLA-Latent: Scaling Robotic Manipulation Foundation Models with 3D-Grounded Latent Actions

Learns 3D-grounded latent actions from raw video, then uses them as a shared pretraining target for a VLA before robot-specific action alignment.

arXiv ↗Oct 25, 2026Code ↗

  • robotics
  • robot manipulation
  • vision-language-action
  • latent actions
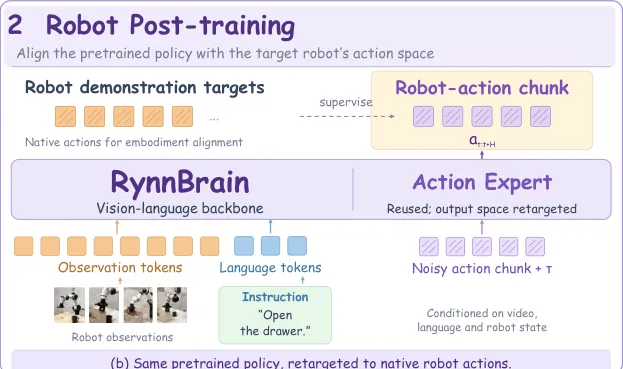
Pipeline diagram showing robot post-training method with RynnBrain and action expert

What it is

Pretrains robot policies from heterogeneous videos by learning 3D-grounded latent actions, then retargets the pretrained model to robot-specific controls. Instead of relying on scarce action-labeled demos or forcing incompatible control spaces together, it learns 3D-grounded latent actions from video transitions and trains a VLA to predict them, then adapts that pretrained policy to each robot's native actions.

Key results

  • 98.8% success on LIBERO
  • 84.7% on LIBERO-Plus without benchmark-specific adaptation
  • 88.6% average success on RoboTwin 2.0 bimanual benchmark

Shows latent-action supervision can scale robot policy pretraining beyond native action-labeled data across embodiments.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.