
What it is
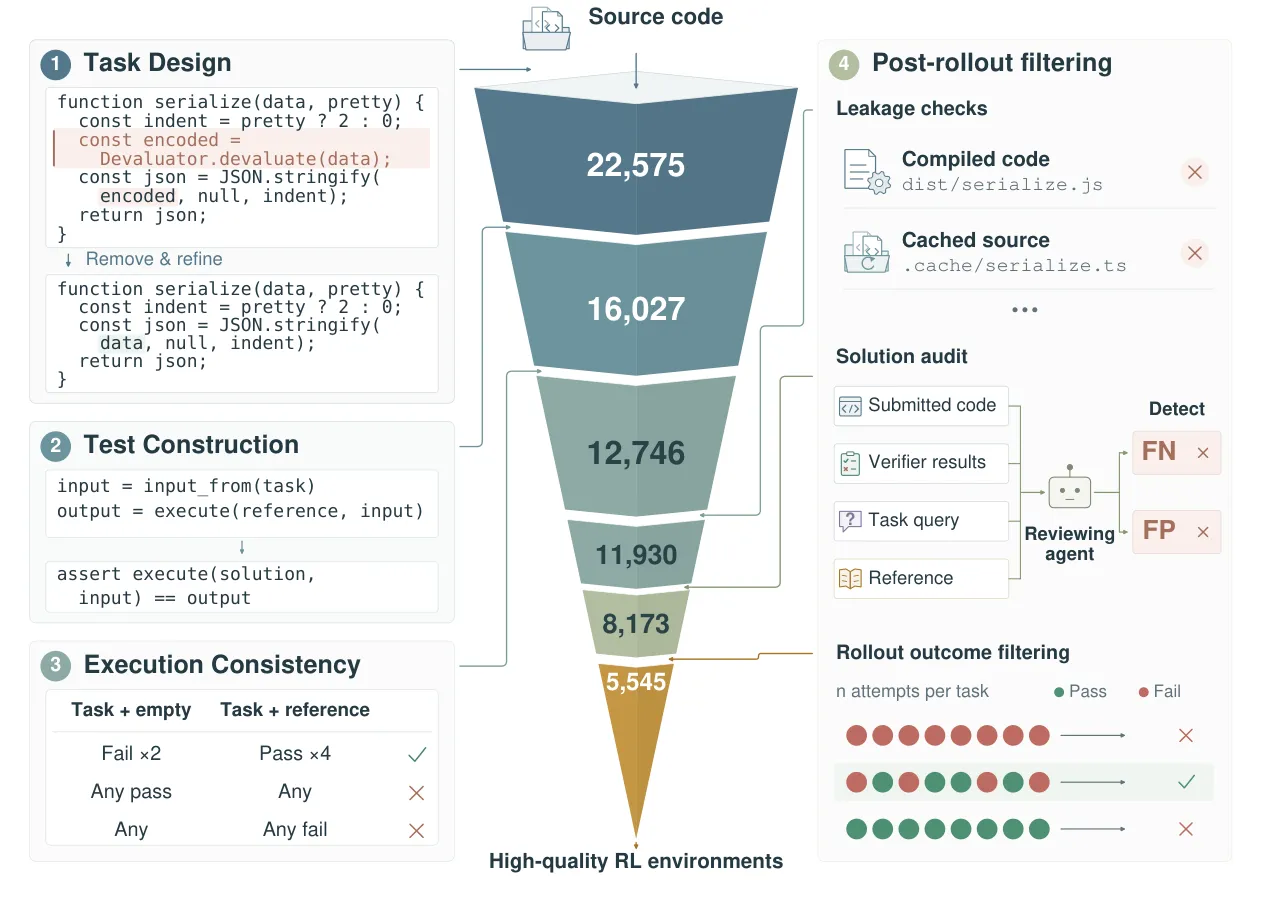
Builds coding RL environments directly from source code by extracting implemented functionality, synthesizing tests, and filtering tasks for reliable execution rewards. Instead of relying on issues, commits, tests, or docs, it turns code itself into RL tasks: agents infer behavioral specs from existing functionality, build execution-grounded tests, and aggressively filter for leakage and verifier defects.
Key results
- DeepSWE pass rate rose 10.0%→21.7% (+11.7 pp)
- ProgramBench Almost Solved rose 4.5→21.5 (+17.0 pp)
- Terminal-Bench v2.1 pass rate rose 63.7%→72.2% (+8.5 pp)
Shows that implemented functionality in real codebases can be converted into reliable RL training tasks that transfer across diverse coding-agent benchmarks.