Dataset

UltraData-Code

Contains file-level code records and synthesized programming exercises derived from real implementations for multilingual code model pretraining.

Hugging Face ↗Sep 5, 2026Paper ↗

  • llm
  • code-pretraining
  • algorithmic-code
  • synthetic-data
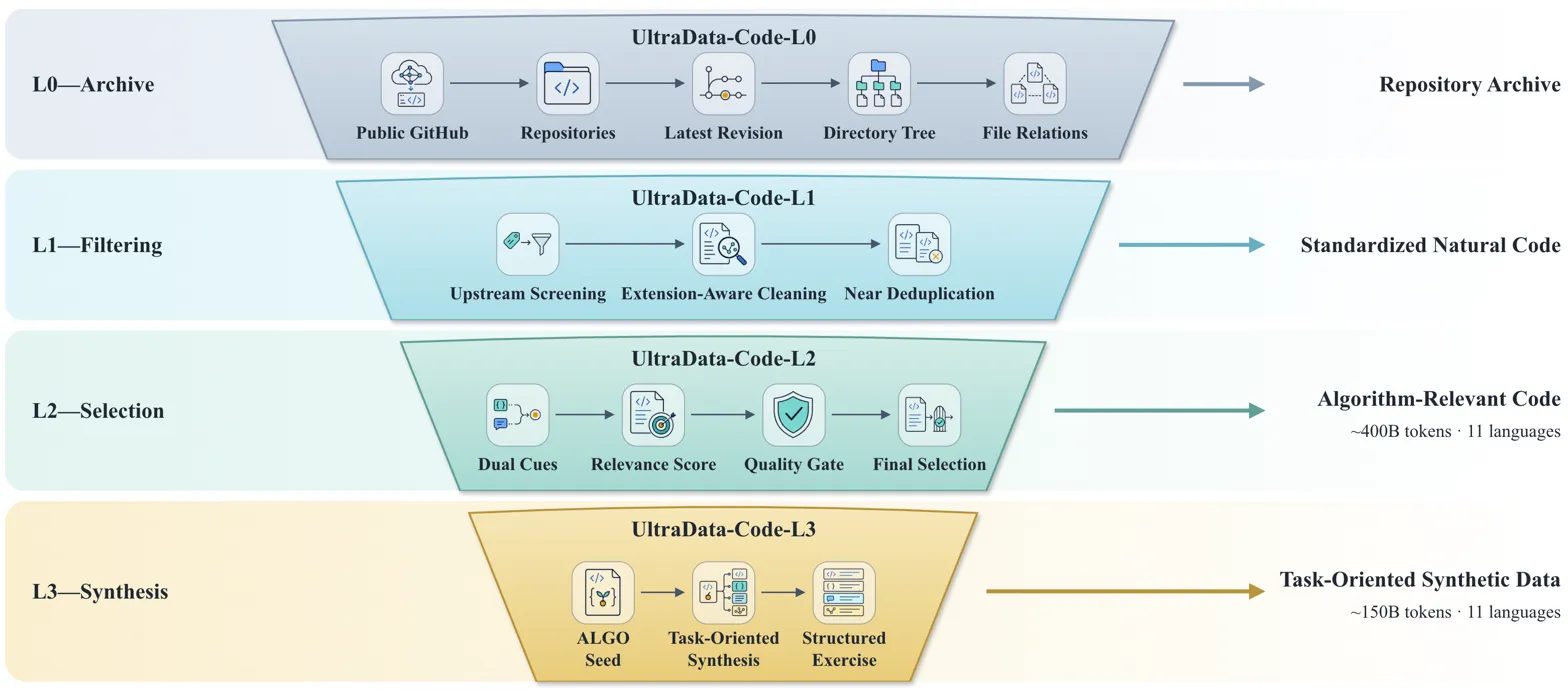
Multi-stage data pipeline diagram showing L0-L3 processing stages and outputs

What it is

Tiered code pretraining corpus with 400B algorithmic-code tokens and 150B synthesized programming-exercise tokens across 11 languages. ~550B tokens across 2 released tiers and 11 languages: L2 file-level algorithmically relevant code with role/relevance/quality scores, plus L3 implementation-grounded task, analysis, solution, and test records.

Key results

  • ~400B L2 tokens + ~150B L3 tokens
  • 11 programming languages
  • Apache-2.0 dataset; source repo licenses also apply

Useful for pretraining and ablation studies on code generation with natural code versus synthesized task data.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.