Dataset

arXiv Complete Corpus

Contains 3.15M arXiv papers with metadata, version history, resolved TeX, source packages, LaTeX files, PDFs and PS for retrieval or LM work.

Hugging Face ↗Sep 10, 2026Paper ↗Code ↗

  • llm
  • nlp
  • scientific-papers
  • latex
  • full-text
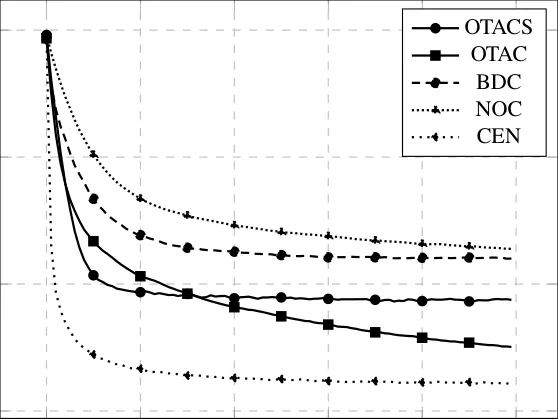
Comparative performance curves of proposed method (OTACS) vs baselines showing core claim

What it is

A 16.08 TB snapshot of arXiv with metadata, version history, source files, LaTeX, PDFs, and resolved TeX for 3.15M papers. ~3.15M arXiv papers across 9 parquet configs: metadata, 5.03M versions, 54.6M indexed files, 2.86M resolved TeX texts, plus source, LaTeX, PDF and PS contents with paths, sizes and SHA-256 digests.

Key results

  • 3,148,796 papers and 5,030,612 reported versions
  • 54,597,326 indexed files; 2,856,227 resolved TeX rows
  • 16.08 TB parquet snapshot; mixed per-paper licenses

Useful for training and evaluating scientific retrieval, full-text modeling, and version-aware document pipelines.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.