
What it is
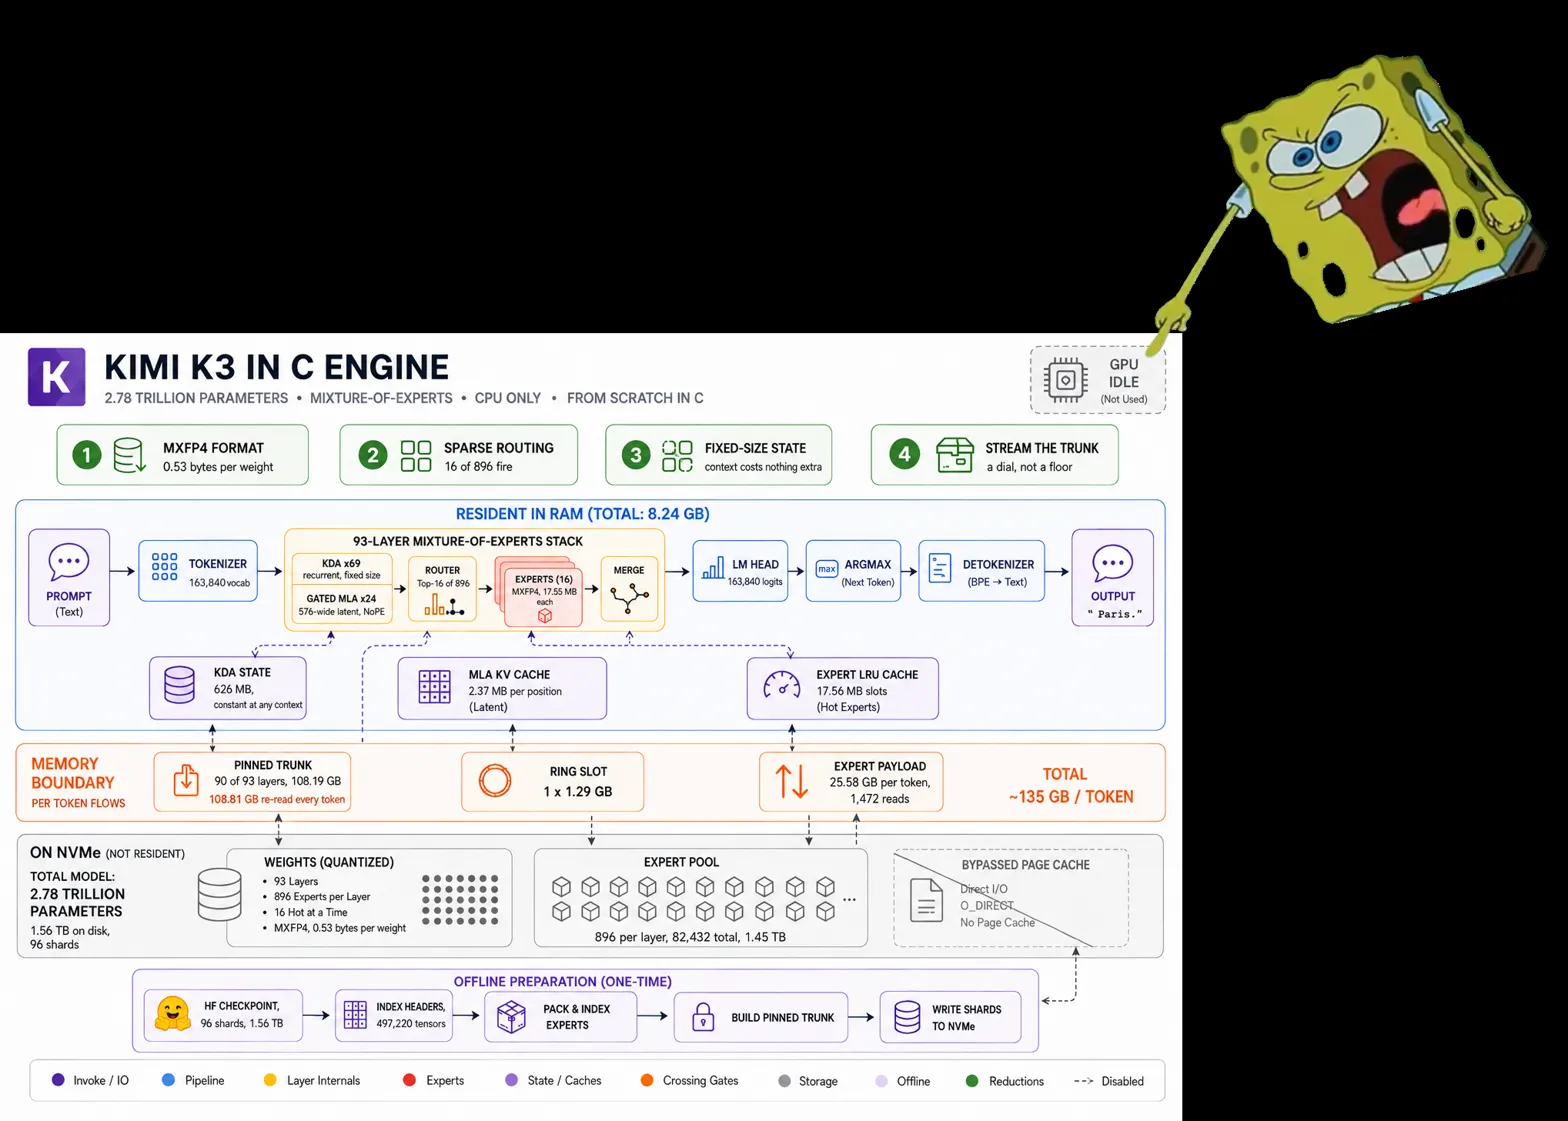
Runs Kimi K3 CPU inference from a 1.56 TB checkpoint in 8.24 GB RAM using a tiny portable C99 engine with streamed trunk layers and on-demand MoE experts. Run a 2.78T-parameter MoE model on one CPU with 8.24 GB peak RAM by streaming dense trunk layers from disk and loading only routed experts on demand.
Key results
- 2.78T params, 1.56 TB checkpoint, 8.24 GB peak RSS measured
- 176 KB engine binary; depends only on libm and OpenMP
- Server preset pins 90/93 trunk layers at ~19-21 s/token
Shows that exact inference for trillion-parameter MoE models is possible on a single CPU when only active experts and a streamed trunk are kept resident.