Paper

DAPD: Dual-Anchored Policy Distillation

Matches teacher and student information during on-policy distillation using a self-conditioned anchor and two-way reference/rollout supervision.

arXiv ↗Aug 3, 2026Code ↗

  • llm
  • policy distillation
  • post-training
  • reasoning
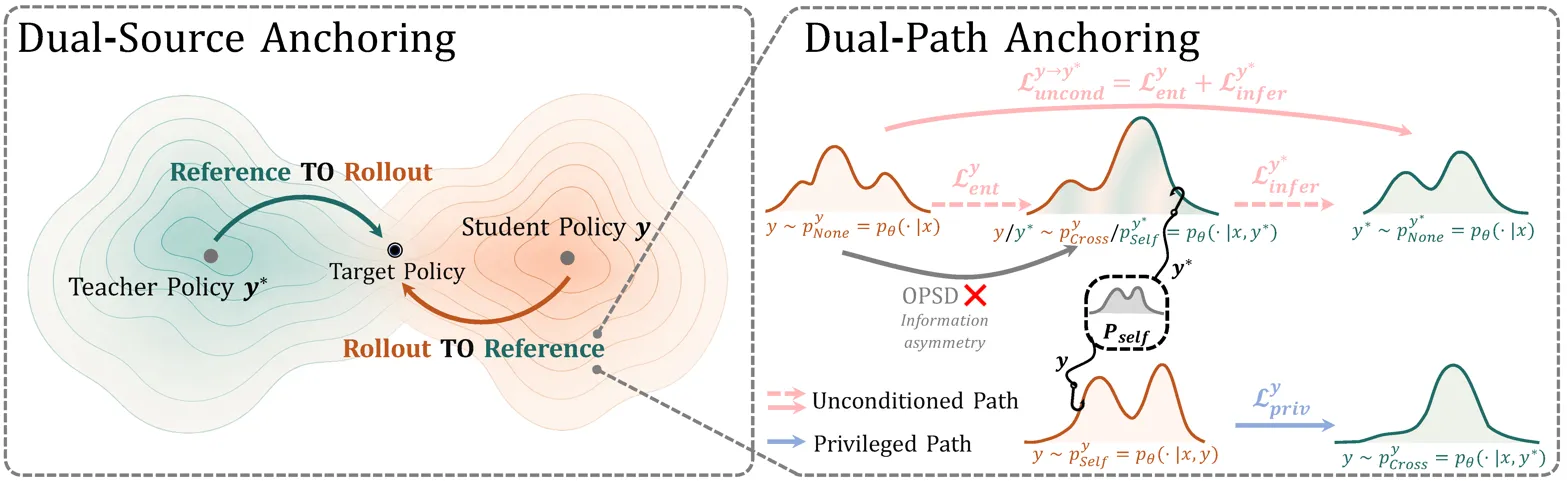
Method diagram showing dual-source and dual-path anchoring approach with loss functions

What it is

Fixes privilege illusion in on-policy LM distillation by matching teacher and student information with dual anchors and bidirectional guidance. Instead of filtering a privileged teacher signal, it matches teacher/student information during distillation. A self-conditioned bridge anchors both unprivileged and privileged paths, and supervision runs in both reference→rollout and rollout→reference directions.

Key results

  • +2.00 Avg over OPSD on Qwen3-4B across 6 benchmarks
  • Qwen3-4B: 57.34 avg vs 55.34 for OPSD
  • Scale gains over OPSD reach +2.69 at 4B and +2.78 at 32B

Privilege illusion in on-policy self-distillation is mainly caused by teacher-student information mismatch, and fixing that mismatch improves post-training reliably.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.