Paper

WorldCycle: Self-Verifiable Reinforcement Learning for Long-Horizon Video World Models

Uses reversible action cycles as self-verifiable RL targets for video world models, rewarding within-cycle closure and cross-cycle consistency instead of only local action following.

arXiv ↗Aug 5, 2026

  • llm
  • multimodal
  • world models
  • reinforcement learning
  • video generation
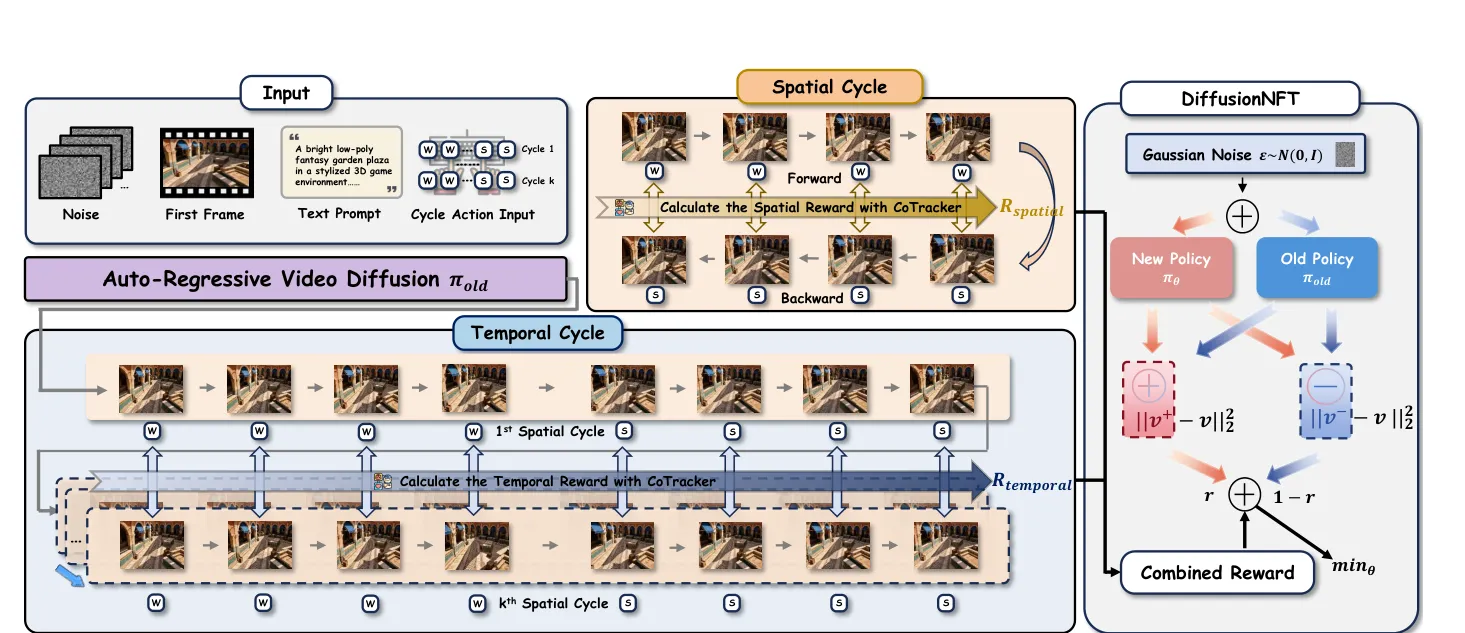
Full method pipeline showing spatial/temporal cycles, reward calculation, and DiffusionNFT policy training

What it is

Self-verifiable RL for video world models using reversible action cycles as label-free long-horizon supervision. It trains on cycle closure and repeated-cycle consistency to reduce rollout drift. Instead of short-horizon clip rewards with no long-term verifier, it uses reversible action cycles whose inverse must return to the start. RL optimizes dense mirrored-cycle closure and repeated-cycle consistency, including OOD composite actions, without ground-truth futures.

Key results

  • Up to 44% lower state-returning drift vs the base model
  • Nearly 4× higher composite-action accuracy than the base model

Closed reversible trajectories can provide exact, annotation-free supervision for long-horizon world-model correctness.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.