
What it is
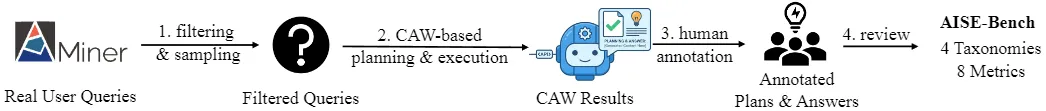
Human-verified benchmark for academic KG information seeking with executable API traces and grounded answers for evaluating tool-using LLM agents. 500 test examples from authentic AMiner queries, plus 868 more current annotations, each with question, gold multi-step API plan, standardized inputs, API outputs, and human-edited grounded answers.
Key results
- 500 examples in the default test split
- 1,368 current examples across 3 JSON files
- Bilingual data: English and Chinese; MIT license
Useful for benchmarking LLM agents on academic search, multi-step tool use, and grounded QA.