Repo

lingbot-video

Generates T2I, T2V, and TI2V outputs for embodied scenarios using structured JSON prompts, optional auto-negative prompts, and a refiner stage.

GitHub ↗Jul 8, 2026Paper ↗

  • multimodal
  • video-generation
  • mixture-of-experts
  • embodied-intelligence
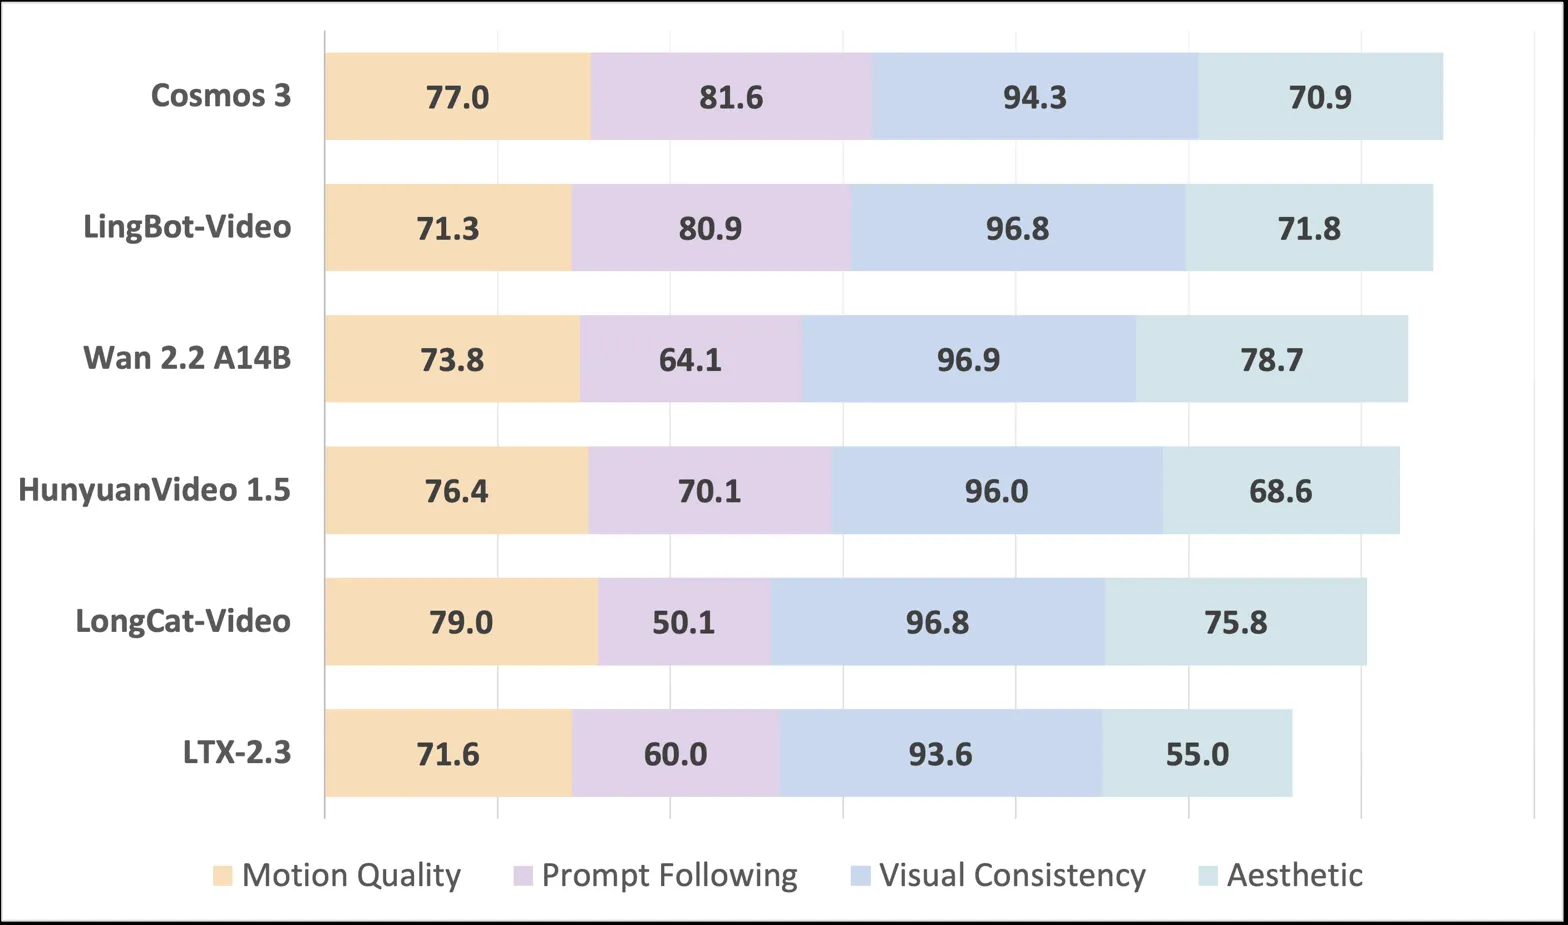
Comparative benchmark of methods across quality metrics, showing core performance claims

What it is

Open-source MoE video generator for embodied tasks with T2I, T2V, and TI2V pipelines, prompt rewriting, and refiner support. Claims ~3× faster inference and top open-source RBench score. Generate embodied-focused images and videos from text or a first frame, with a prompt rewriter, auto-negative prompts, and optional refiner across diffusers or SGLang backends.

Key results

  • Claims ~3× faster inference from its MoE architecture
  • Supports T2I, T2V, TI2V, and refinement in released checkpoints
  • Top open-source RBench score: 0.620 avg as of Jul 9, 2026

Shows that large open MoE video models can target embodied world understanding while staying competitive on public benchmarks.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.