
What it is
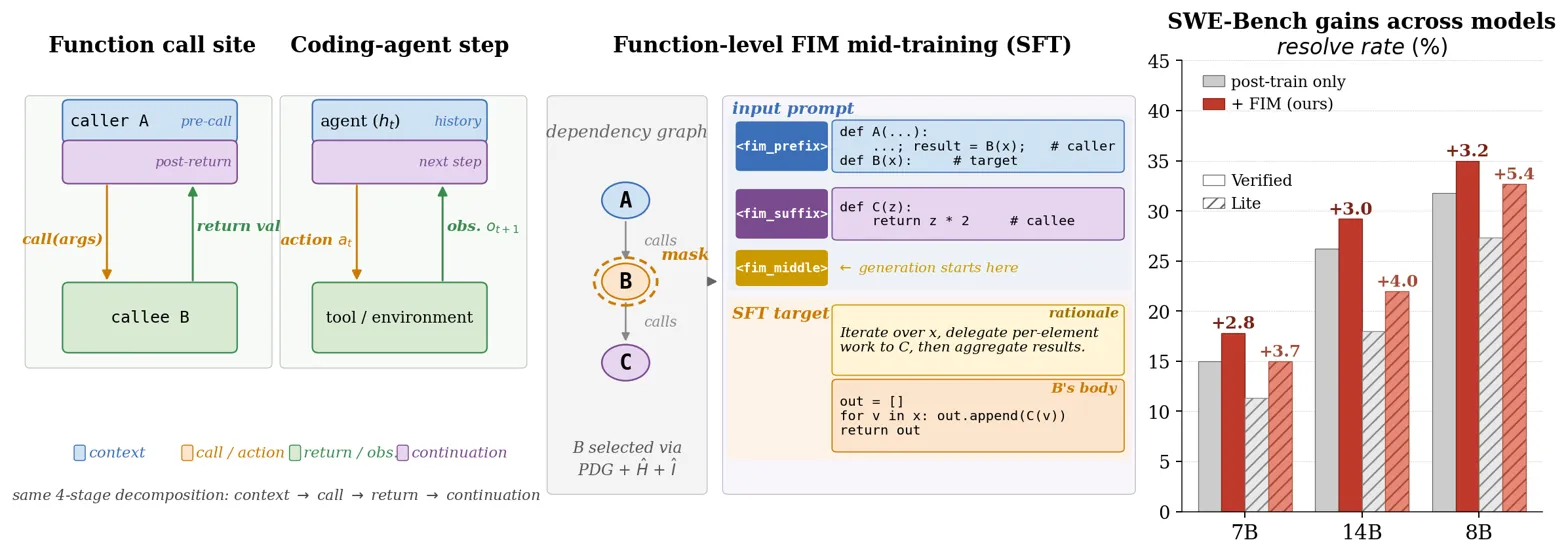
Mid-trains code LLMs with function-aware FIM so they learn to use returned context like tool outputs before agent fine-tuning. Instead of random-span FIM or pure left-to-right code pretraining, masks whole functions chosen by PDG plus complexity/inferability scores, and trains the model to reconstruct them with rationale from surrounding code.
Key results
- Qwen3-8B + SWE-Lego: 35.0 Verified, +3.2 over post-train only
- Qwen2.5-14B + R2E-Gym: 29.2 Verified, +3.0 over reproduced baseline
- 14B restores +11.1 LiveCodeBench and +3.9 tau-bench vs post-train only
Training on function-call structure before agent tuning improves tool-return conditioning and reduces the capability loss from agentic post-training.