
What it is
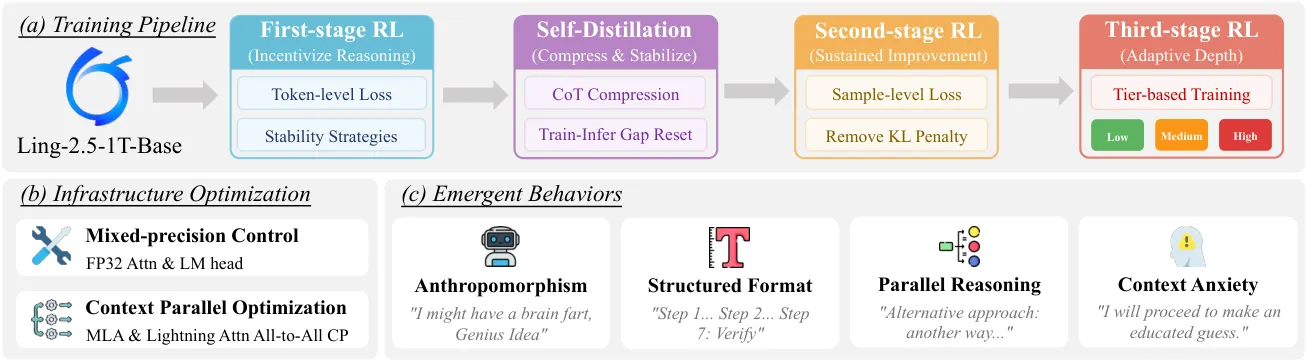
Scales zero-data RL with verifiable rewards to a 1T-parameter LLM using a minimal, stabilized pipeline for concise, high-quality reasoning. Instead of adding hand-crafted reasoning heuristics, it scales zero RL to 1T with a simple staged pipeline: clipped IS with train-infer ratio correction, self-distillation to compress CoT, then sample-level and tiered RL for adaptive depth.
Key results
- 1T model shows higher sample efficiency than its 104B counterpart
- Competitive performance on 7 challenging mathematical benchmarks
- Better CoT quality with clearer, more concise traces under 3-dim eval
At trillion scale, simple stabilized zero-RL can elicit stronger and more structured reasoning than hand-crafted prompting heuristics.