Repo

OpenCoF

Teaches video generators to solve reasoning tasks through generated frame sequences using a 17,312-video dataset plus optional visual or textual reasoning tokens.

GitHub ↗Jul 10, 2026Paper ↗

  • multimodal
  • video-generation
  • reasoning
  • dataset
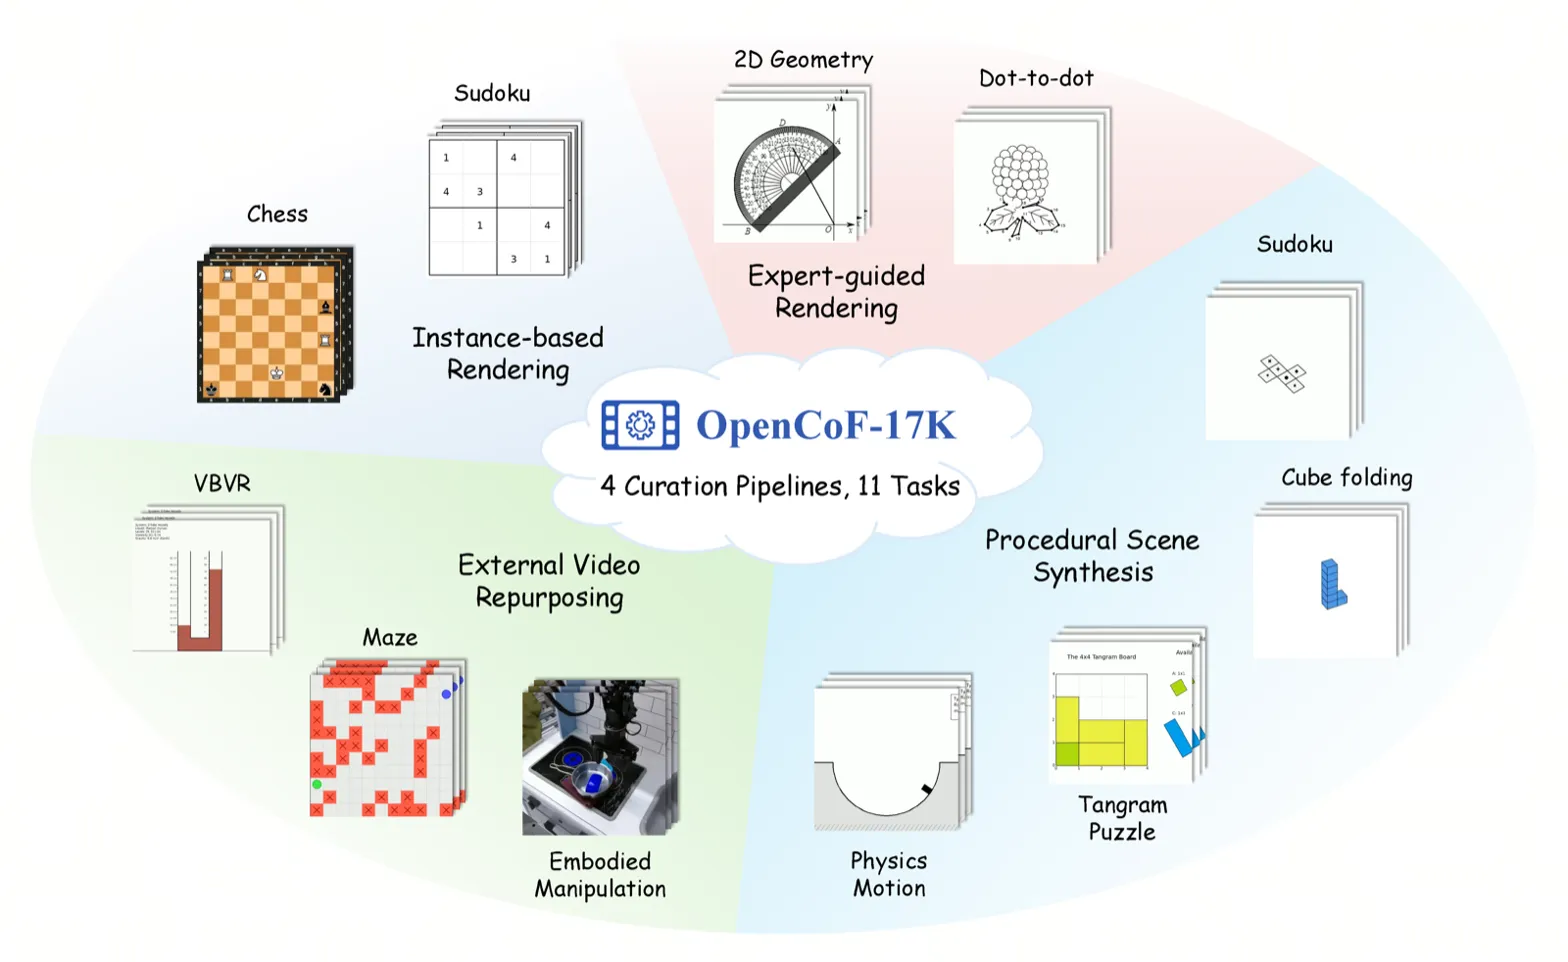
Taxonomy showing dataset's 4 curation pipelines and 11 tasks with examples

What it is

Framework and 17K-video dataset for training video generators to reason through temporally connected frames, with gains on four video-reasoning benchmarks. Train image-to-video models for reasoning using a 17,312-video supervision set and optional visual or textual reasoning tokens that organize intermediate reasoning state.

Key results

  • OpenCoF-17K contains 17,312 videos across 11 reasoning task families
  • Improves Wan2.2-I2V-A14B on MME-CoF, Gen-ViRe, VIPER, and RULER-Bench
  • Adds two token designs, vt and tt, for visual cues and semantic priors

Shows video generation can serve as a reasoning process when trained with temporal supervision and explicit intermediate-state tokens.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.