Paper

Read It Back: Pretrained MLLMs Are Zero-Shot Reward Models for Text-to-Image Generation

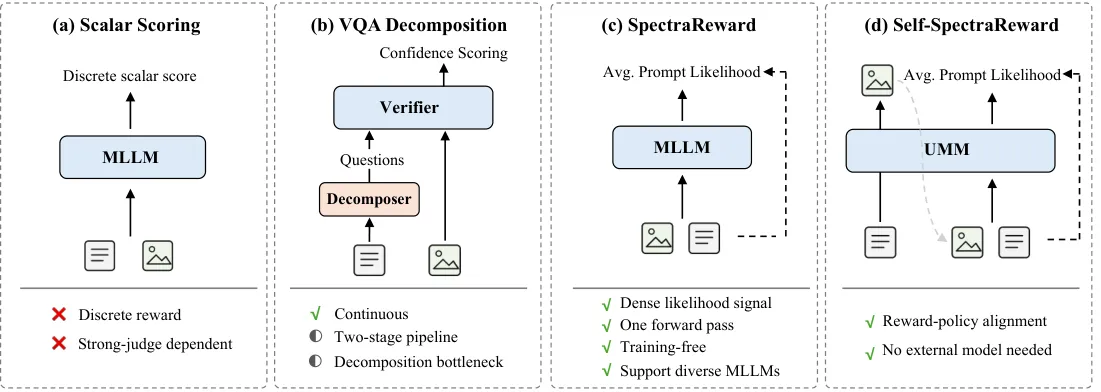
Uses prompt reconstruction likelihood as reward, not judge scores or decomposed checks. A self-reward version reuses the model's own understanding branch.

arXiv ↗Jul 13, 2026

  • cv
  • multimodal
  • text-to-image
  • reinforcement learning
  • reward modeling
Compares method variants showing pipeline design and advantages of proposed approach

What it is

Turns pretrained MLLMs into training-free reward models for text-to-image RL by scoring how well the prompt can be read back from a generated image. Instead of scalar judging or VQA decomposition, it uses image-conditioned prompt log-likelihood from a single teacher-forced MLLM pass as reward. A self-reward variant uses a UMM's own understanding branch, avoiding external reward models.

Key results

  • +10.0 TIIF-Bench and +5.5 GenEval vs BAGEL at 512px
  • Beats AlphaGRPO by +6.3 TIIF-Bench and +3.3 GenEval at 512px
  • Self-SpectraReward hits 89.8 GenEval and 34.3 GenEval2 at 1024px

Shows reward-policy alignment can matter as much as reward model scale for text-to-image RL.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.