Paper

Weak-to-Strong Generalization via Direct On-Policy Distillation

Rather than copy a weak teacher, it transfers the teacher's pre/post-RL policy difference as reward-like supervision on the student's own trajectories.

arXiv ↗Jul 8, 2026

  • llm
  • nlp
  • reasoning
  • reinforcement learning
  • distillation
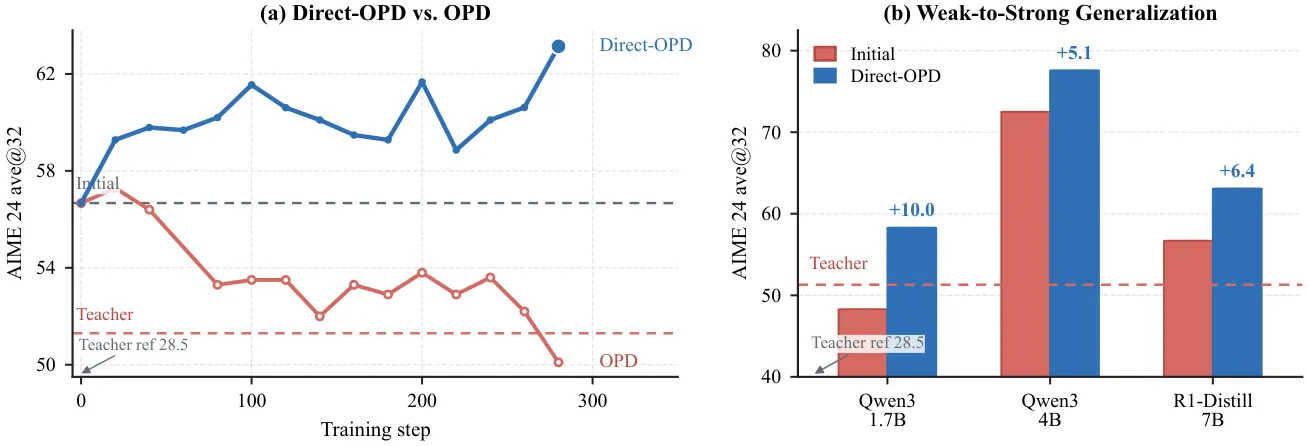
Comparative results showing Direct-OPD beats OPD and weak-to-strong generalization gains

What it is

Transfers RL gains from a cheap weak model to a stronger LM by distilling the teacher's pre/post-RL policy shift on the student's own rollouts. Instead of imitating a weak post-RL teacher, it distills the teacher's RL-induced log-policy shift versus its pre-RL checkpoint as a dense implicit reward on the stronger student's on-policy states.

Key results

  • Qwen3-1.7B: 48.3% -> 58.3% on AIME 2024 with Direct-OPD
  • R1-Distill-7B: 56.7% -> 63.1% on AIME 2024, above the 51.3% teacher
  • Qwen3-4B: 72.5% -> 77.6% on AIME 2024 despite already beating the teacher

RL outcomes can be reused across model scales as transferable reward signals, not just as weak policies to imitate.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.