Paper

Ideas Have Genomes: Benchmarking Scientific Lineage Reasoning and Lineage-Grounded Idea Generation

A genome-centric benchmark that replaces paper-level links with typed idea objects and diffs, then evaluates lineage reasoning and lineage-conditioned proposal generation.

arXiv ↗Jul 9, 2026Code ↗

  • llm
  • benchmarks
  • scientific reasoning
  • evaluation
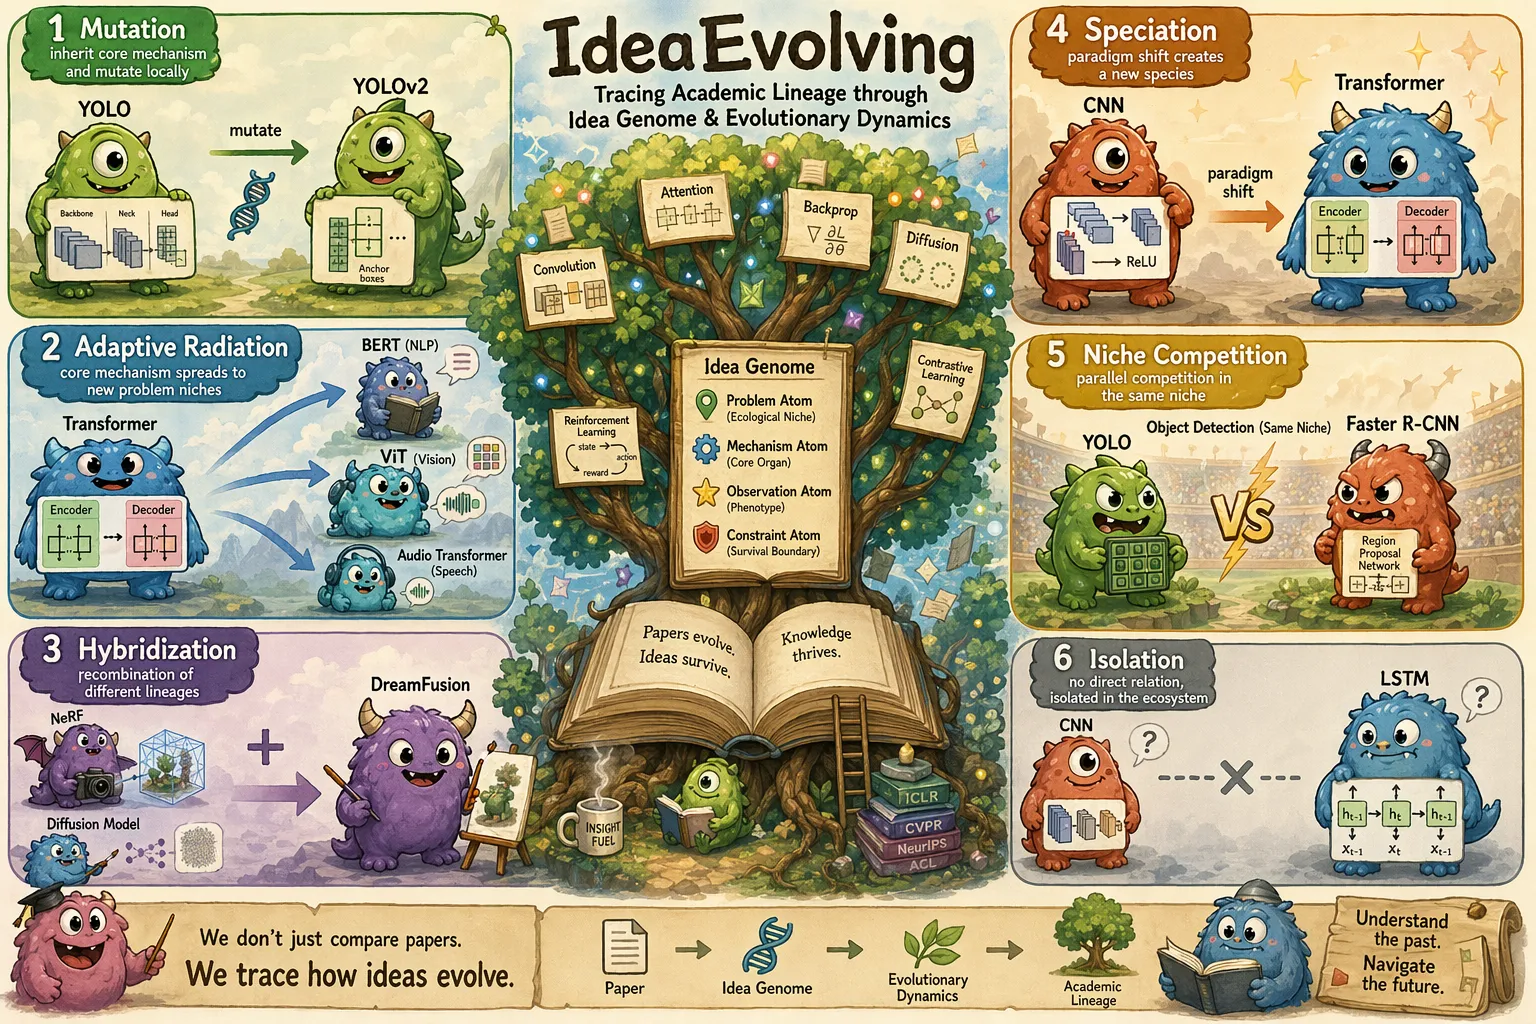
Conceptual framework diagram explaining the idea-evolution method and its core mechanisms

What it is

A benchmark for testing whether LLMs can trace how scientific ideas inherit, mutate, and recombine, and generate lineage-coherent proposals. Instead of paper-level relevance or free-form ideation, it evaluates science at idea-object level: papers are decomposed into typed Idea Genomes and aligned with GenomeDiffs to test inheritance and score descendant proposals.

Key results

  • Best IG-Exam exact accuracy is 27.3% across 1,029 lineage tasks
  • IG-Exam covers 42 task types and 1,029 instances across 4 capability axes
  • IG-Bench includes 1,961 lineage traces, 1,085 idea objects, 920 diffs

Shows that fluent literature-aware generation does not imply the ability to track and extend mechanism-level scientific lineage.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.