Paper

Scaling Properties of Text Conditioning in Visual Generation

Structured prompts replace verbose natural language with typed image-grounded fields, and an LLM prompter learns to write them from user requests.

arXiv ↗Jul 31, 2026Code ↗

  • cv
  • text-to-image
  • diffusion models
  • prompt engineering
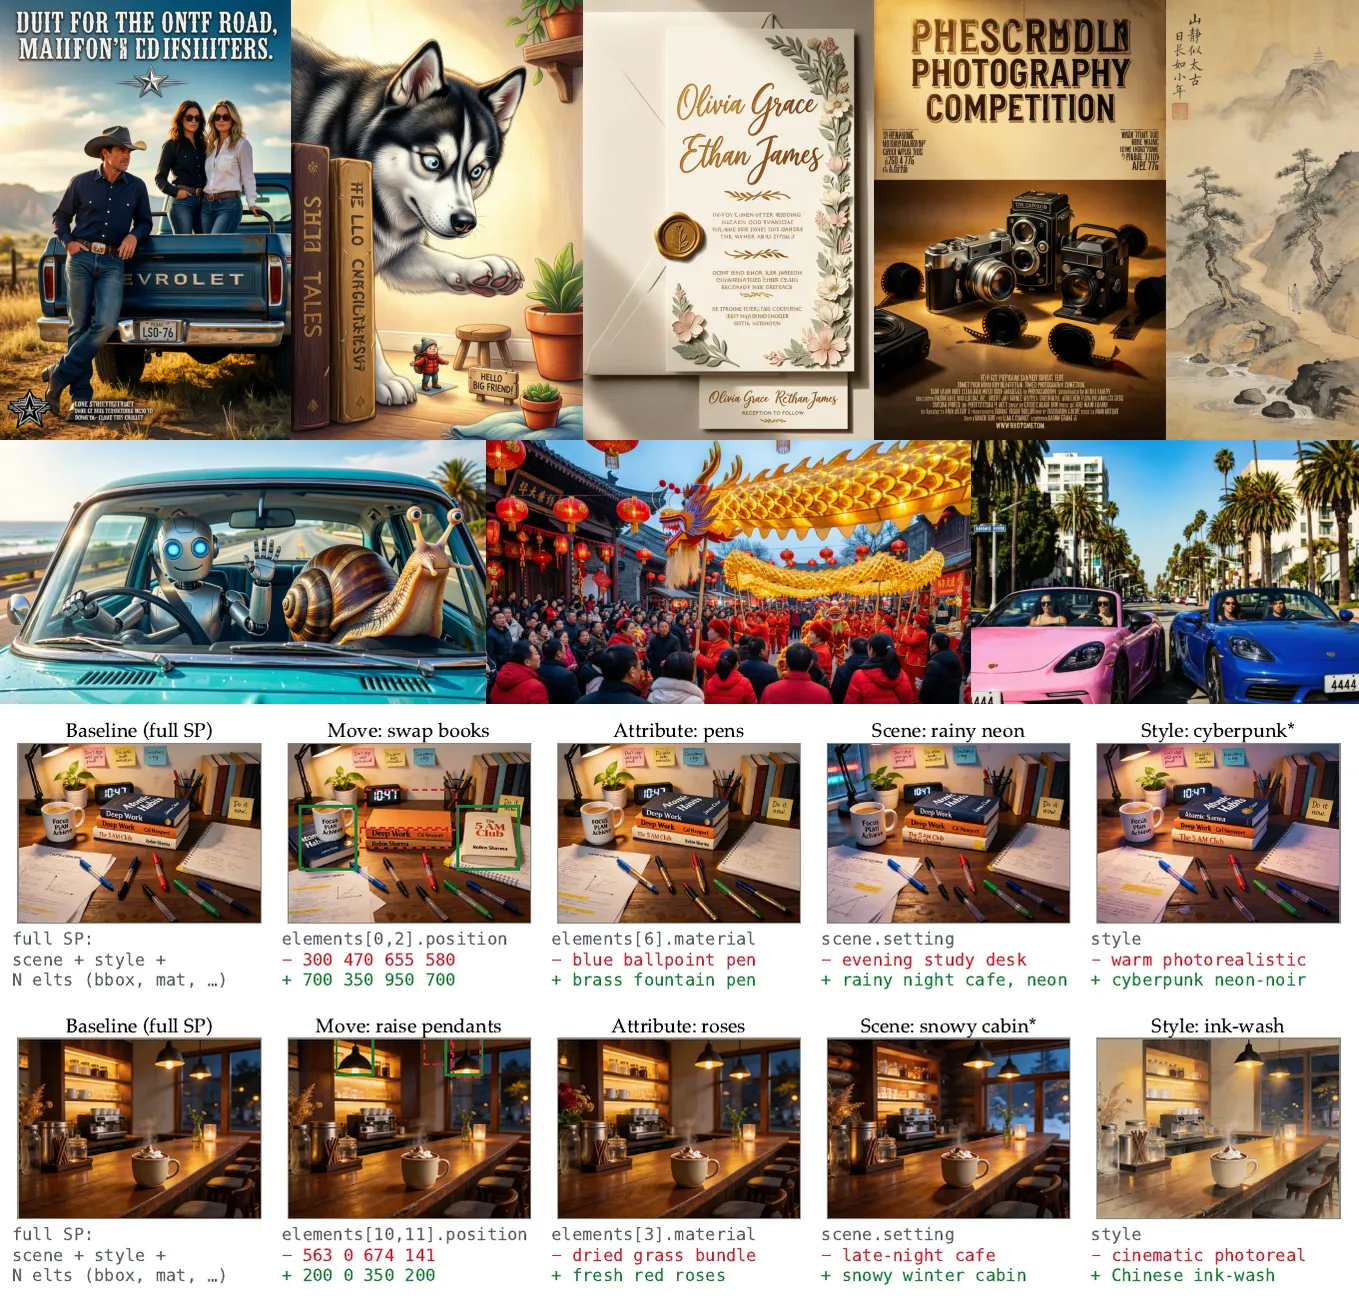
Composite showing generated outputs plus structured editing controls (move, attribute, scene, style)

What it is

Measures how caption information, not length, scales diffusion training, then uses structured JSON prompts plus a trained LLM prompter to improve text-to-image generation. Instead of longer prose prompts, it uses image-grounded structured JSON prompts whose informativeness predicts diffusion loss. A separate LLM prompter learns to map user text into this schema, improving both training-side supervision and inference-time prompting.

Key results

  • Diffusion loss vs GPG fits linearly with r=0.984 across controlled runs
  • SP reconstructions improve to DINOv3 0.65 vs 0.51 for long NL captions
  • SP reconstructions cut LPIPS to 0.59 vs 0.68 for long NL captions

Shows that image-grounded prompt information, not token count, is the variable that scales text conditioning for diffusion models.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.