Paper

Scalable Visual Pretraining for Language Intelligence

Uses raw rendered scientific pages, not parsed text, for autoregressive next-latent pretraining. No OCR or paired image-text supervision is needed.

arXiv ↗Jul 10, 2026

  • cv
  • llm
  • multimodal
  • document understanding
  • scientific reasoning
  • self-supervised learning
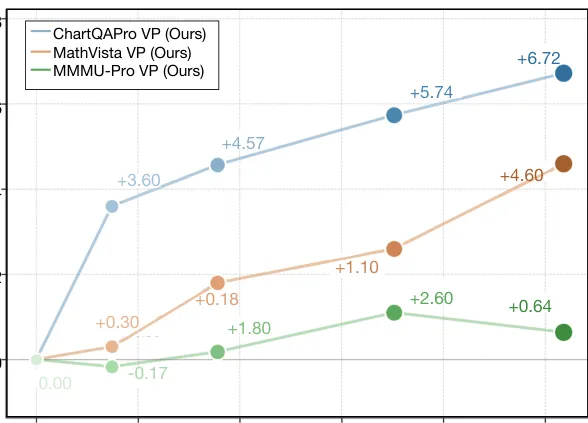
Shows performance gains across benchmarks, core comparative result of the method

What it is

Pretrains foundation models directly on rendered document pages instead of parsed text, using the same corpora. This visual route improves scientific reasoning and multimodal transfer. Instead of textualizing PDFs and losing layout, equations, and figures, it pretrains on raw document pages with next visual-latent prediction. Unlike paired multimodal training, it needs no OCR or image-text supervision and still boosts language reasoning.

Key results

  • Qwen3.5 GPQA: 79.29 vs 76.24 with text pretraining (+3.05)
  • Llama3.2 Vision AIME: 18.54 vs 13.75 with text pretraining (+4.79)
  • VP uses ~20B visual tokens vs ~80B text tokens for matched PDFs

Native visual structure in documents carries reasoning-relevant information that text extraction drops, and models can learn it efficiently without paired supervision.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.