
What it is
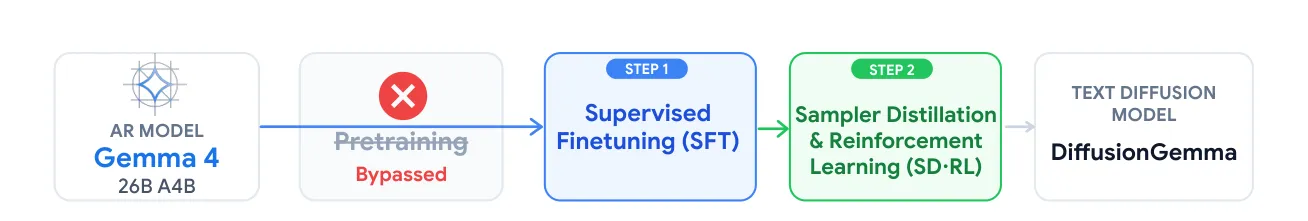
An open-weight LLM that swaps token-by-token decoding for discrete diffusion over 256-token blocks, delivering much faster text generation from a fine-tuned Gemma 4 base. Instead of training a text diffusion model from scratch or decoding sequentially, it fine-tunes Gemma 4 into a bidirectional discrete diffuser that denoises 256-token blocks in parallel, then uses RL plus sampler distillation to cut denoising steps while keeping AR and multimodal abilities.
Key results
- ~1,500 output tokens/s on 1× H100 across the eval suite
- ~20 tokens per forward pass vs ~3-6 for speculative AR decoding
- Uses <10% of the starting AR model's total training token budget
Shows an AR LLM can be converted into a high-speed diffusion generator with modest extra training while preserving much of the base model's functionality.