Paper

Deferred Exposure of Future Trajectories for Verifiable Reasoning in Autonomous Driving VLMs

Defers trajectory-option exposure until after scene-only decision making, then matches that decision to explicit candidates for verifiable training.

arXiv ↗Aug 3, 2026Code ↗Dataset ↗

  • llm
  • multimodal
  • autonomous driving
  • reasoning
  • reinforcement learning
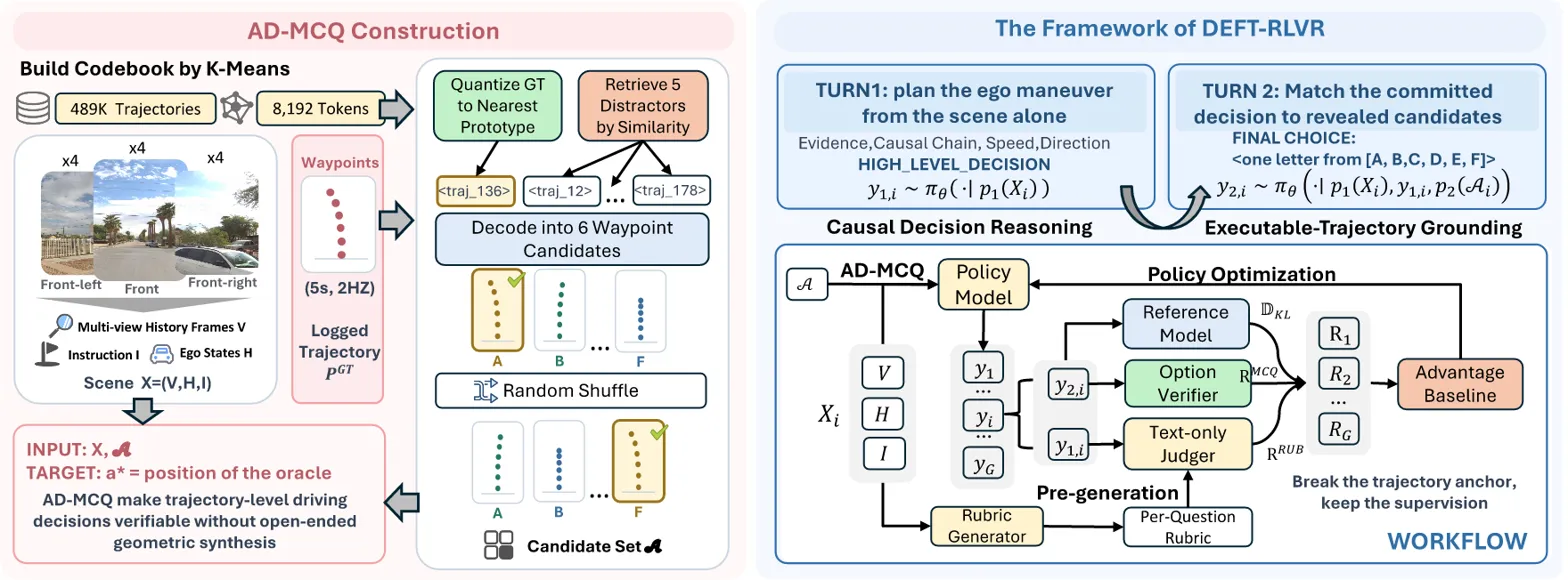
Two-panel pipeline showing AD-MCQ construction and DEFT-RLVR framework workflow

What it is

Turns driving planning into a verifiable multiple-choice trajectory task and trains VLMs to reason before seeing options, reducing trajectory anchoring bias. Instead of exposing future trajectories during reasoning, it hides them until after the model commits to a scene-based decision. Planning becomes MCQ over explicit trajectory candidates, enabling exact verification and RL on causally grounded CoTs.

Key results

  • 77.9% ACC vs 28.1% base on AD-MCQ with Qwen3-VL-8B
  • 82.2% ACC vs 34.0% base on AD-MCQ with Qwen3.5-4B
  • 49.5% vs 39.6% ACC on OOD nuScenes with Qwen3-VL-8B

Shows that information order matters: reasoning first and grounding later yields more faithful and transferable driving decisions.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.